mirror of
https://github.com/cozystack/cozystack.git
synced 2026-10-30 00:27:04 +09:00
feat/postgres-credentials
2735
Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 Timofei Larkin |
66a20d9a0a |
docs(postgres): describe minted passwords
The README told users to read a password from <release>-credentials, which the chart no longer renders, the createRole text named the init job as the place a planted role is refused, and the restore notes described the init job applying chart-generated passwords. They now describe the mint, the pre-upgrade check, how a restored copy gets its passwords, and why a downgrade past the conversion is unsupported. Assisted-by: LLM Signed-off-by: Timofei Larkin <lllamnyp@gmail.com> |
||
|
Timofei Larkin
|
2fac379457 |
feat(postgres)!: mint tenant passwords through the credentials API
The chart generated every user's password at render time into <release>-credentials, which tenants could read again at any time and which Helm history kept for MaxHistory revisions, so a deployment whose policy requires a credential shown once could not run PostgreSQL here. The accounts move under CloudNativePG's managed roles, each pointing at the account Secret the Cozystack API seeds, so the operator creates the role with the SCRAM verifier the Secret holds and applies a changed Secret live, and a password set inside PostgreSQL is reverted. Every role is rendered as the init-script created it, because the operator reverts an attribute that differs, revokes a parent role missing from inRoles and clears a comment the spec leaves unset, while the init-script still finds the roles to drop by that comment and by membership in the marker. The init-script stops creating, passwording and altering accounts, where it would be a second writer, and keeps the two things the operator has no field for: the marker membership narrowed to a record, and createrole_self_grant. The refusal to adopt a role the chart did not mark moves into a pre-upgrade hook, because the operator adopts a managed role within seconds of the spec reaching it and the post-upgrade init-job would find it adopted already. The definition declares the credentials block, so the API seeds, serves and mints for the kind, and no longer selects the credentials Secret, which the chart no longer renders or grants. BREAKING CHANGE: PostgreSQL passwords are no longer readable from <release>-credentials. A password is issued once, by a mint on the account's Credential in core.cozystack.io, and replaced by the next mint; deleting a Postgres application whose release is suspended is refused. The conversion needs a platform variant with migrations enabled. Assisted-by: LLM Signed-off-by: Timofei Larkin <lllamnyp@gmail.com> |
||
|
Timofei Larkin
|
e7d5724de5 |
fix(monitoring-agents): indent extra outputs like the rest
The extra outputs were indented again after the block scalar had been dedented, six columns deeper than the VictoriaLogs outputs, and fluent-bit refuses a config whose indentation is inconsistent, which stops every output, not only the added one. The test now pins the indent instead of matching any whitespace. The credentials and specschema packages join the unit-test target, so their tests run in CI, and the audit-log page names the field the pipeline writes. Assisted-by: LLM Signed-off-by: Timofei Larkin <lllamnyp@gmail.com> |
||
|
Timofei Larkin
|
c77daaba85 |
docs(api): cut comments to what the code cannot say
Comments carry the mechanism, not the rationale; every argument removed here is in the design proposal or the PR. Where one claim appeared at several sites, the copy at the site that constrains the code stays. Assisted-by: LLM Signed-off-by: Timofei Larkin <lllamnyp@gmail.com> |
||
|
Timofei Larkin
|
108b51df3d |
feat(api): serve credentials with mint and revoke, and seed accounts
The Credential view lists the account Secrets of the namespace by label and skips any no live HelmRelease owns, so no kind is served until its definition carries a credentials block. A mint replaces the stored value in one conditional write keyed on the Secret's resourceVersion and returns the plaintext once; a revoke discards it. Both record an Event on the application, which needs create on events. The application registry seeds an account Secret per declared account before it writes the HelmRelease, so the chart can reference them from the first render, prunes the Secrets of removed accounts after the write, and refuses to delete an application whose release is suspended, since Flux skips the uninstall and would leave the database running with the Secrets gone. The ApplicationDefinition reconciler computes the per-account valuesFrom entries with the function the API uses, so a release that predates the block gets them on its next reconcile. Schema defaulting moves to a package both can import. A definition declaring a format or an account source that is not built leaves its kind unserved rather than served with passwords the API cannot issue. Tenant roles gain get and list on credentials at view and create on mint and revoke at admin and for the tenant ServiceAccount. Attribution comes from the kube-apiserver audit log, so the operations docs get a policy for distributions that ship none, and monitoring-agents a value for an extra fluent-bit output so a SIEM can receive the log without dropping the VictoriaLogs outputs. Assisted-by: LLM Signed-off-by: Timofei Larkin <lllamnyp@gmail.com> |
||
|
Timofei Larkin
|
0bcded822e |
feat(api): add Credential kinds and the credentials block
Cozystack generates managed application passwords at Helm render time and keeps them in a Secret tenants can read again at any time, which a deployment whose policy requires a credential shown once cannot accept. The accepted design moves generation into the API: an ApplicationDefinition declares its accounts and the stored form of a password in a credentials block, and each account gets a core.cozystack.io Credential whose mint and revoke subresources take a TokenRequest-shaped CredentialRequest. This adds the types, the built-in password formats, which the migration CLI shares so a converted release and a mint store the same form, and the account helpers that name the Secrets and read their record. Design: https://github.com/cozystack/community/blob/main/design-proposals/user-secrets-api/README.md Assisted-by: LLM Signed-off-by: Timofei Larkin <lllamnyp@gmail.com> |
||
|
Alexey Artamonov
|
e8635f6e4b |
build(seaweedfs): stamp the re-pinned in-tree image
The builder, the compile flags and the version stamp changed, so the image built from them has a new digest, and values.yaml has to name it for the components to run that build. Assisted-by: LLM Signed-off-by: Alexey Artamonov <aleksei.artamonov@aenix.io> |
||
|
Alexey Artamonov
|
5592a3f65d |
build(seaweedfs): re-pin the in-tree build from make update
The in-tree build pinned its source, base image and toolchain by hand, and nothing moved them when `make update` vendored a new chart, so a bump would build one release's weed into another release's image, or keep patching a release that already carries the fix. Pin the source archive by checksum and the upstream image by digest as build arguments, compile with the toolchain upstream's own builder uses for the tag, and let `make update` re-pin all of them from the vendored chart and fail when the patches no longer apply. The tests of the patched packages now run once rather than once per target platform, and `weed version` names the build. Assisted-by: LLM Signed-off-by: Alexey Artamonov <aleksei.artamonov@aenix.io> |
||
|
Alexey Artamonov
|
d2c6b85cac |
fix(seaweedfs): run the in-tree SeaweedFS image in every component
With the image keys unset the vendored chart renders chrislusf/seaweedfs at its appVersion, so the patched build from images/seaweedfs would be built and never run, and the S3 gateway would keep being OOM-killed on large GETs. Point every component at the in-tree image, pinned by digest like every first-party reference, and hold that in a unit test so a values change cannot quietly fall back to the upstream binary. Assisted-by: LLM Signed-off-by: Alexey Artamonov <aleksei.artamonov@aenix.io> |
||
|
Alexey Artamonov
|
1913104bd3 |
build(seaweedfs): build SeaweedFS in-tree with a bounded read-ahead
The S3 gateway is OOM-killed while serving a large object. SeaweedFS starts read-ahead downloads after every read of a sequential stream and counts only the downloads it newly starts toward its prefetch window, so a GET reading 256 KiB at a time out of 4 MiB chunks pulls up to about a gigabyte of the object into memory, past the 512Mi limit of the S3 deployment. No SeaweedFS release carries a fix yet, so there is no release to move to instead. Build weed from the 4.45 sources with a patch that keeps the window at the next prefetchCount chunks, and lay it over the upstream image of the same tag so the rest of the image stays upstream's own. The image build runs the tests of the packages the patch touches, including the regression test the patch adds, because go build never compiles them. Assisted-by: LLM Signed-off-by: Alexey Artamonov <aleksei.artamonov@aenix.io> |
||
|
Andrey Kolkov
|
0c2f131192 |
feat(backups): back up Valkey with the Redis strategy
Valkey runs on the same spotahome RedisFailover operator as Redis and speaks the same replication protocol and RDB format, so it needs no strategy kind of its own. The only difference the backup Job sees is the chart's resource-name prefix: valkey-<app> instead of redis-<app> for the sentinel Service and the auth Secret. The Redis driver now accepts applicationRef kind Valkey as well as Redis and hands the template .Release.Prefix, derived from the app's kind, which cozy-default-redis uses for every name it builds. A kind with no known prefix fails the render instead of producing an empty one. cozy-default routes apps.cozystack.io/Valkey to cozy-default-redis. A restore must target an app of the same kind as the backup's source: replaying a Redis dump into Valkey, or the reverse, is not something the strategy can promise across engine releases. The shipped template reads the prefix as `.Release.Prefix | default "redis-"`: during an upgrade the previous controller, which has no Prefix in its render context and serves only Redis, renders the new CR, and a bare reference would print "<no value>" into the names. The redis:8 image already loads RDB v11, which both shipped Valkey versions (7.2, 8.1) write. Signed-off-by: Andrey Kolkov <androndo@gmail.com> Assisted-By: LLM |
||
|
Aleksei Sviridkin
|
3a463609e4 |
feat(bucket): add a ui flag to skip the s3manager web UI (#4881)
<!-- Thank you for making a contribution! Here are some tips for you: - Use Conventional Commits for the PR title: `type(scope): description` - Types: feat, fix, docs, style, refactor, perf, test, build, ci, chore - Scopes are not an exhaustive list — pick the most specific scope for the change and extend the list when a genuinely new area appears. Examples: - System components: dashboard, platform, operator, cilium, kube-ovn, linstor, fluxcd, cluster-api - Managed apps: postgres, mariadb, redis, kafka, clickhouse, virtual-machine, kubernetes - Development and maintenance: api, hack, tests, ci, docs, maintenance - Breaking changes: append `!` after type/scope (`feat(api)!: ...`) or add a `BREAKING CHANGE:` footer - If it's a work in progress, consider creating this PR as a draft. - Don't hesistate to ask for opinion and review in the community chats, even if it's still a draft. - Add the label `kind/backport` if it's a bugfix that needs to be backported to a previous version. --> ## What this PR does Adds a `ui` flag to the Bucket application. Every bucket currently ships an s3manager Deployment, its Service, and an Ingress or HTTPRoute on `<bucket>.<tenant host>`. Tenants that only use the S3 API pay for a pod per bucket and for one DNS name and TLS certificate per bucket, none of which they need. - `packages/apps/bucket`: new `ui` value (default `true`), passed through to the `bucket-system` HelmRelease. The dashboard Role drops its Ingress rule when the UI is off, since an empty `resourceNames` would widen it to every Ingress in the namespace. - `packages/system/bucket`: the Deployment, Service, Ingress and HTTPRoute render only when `ui` is true. With the UI off, the chart no longer requires the tenant apex, as the UI hostname was its only consumer there. - Regenerated `values.schema.json`, `README.md`, `types.go` and the `bucket-rd` ApplicationDefinition. The default keeps existing buckets unchanged. Setting `ui: false` on an existing bucket makes Helm delete the UI objects on the next upgrade; the cert-manager Certificate for the UI host is owned by the Ingress through ingress-shim and goes with it. Tested with `helm unittest` on both charts: new suites cover the default render, `ui: false` behind an Ingress and behind a Gateway, the empty-apex case, the value passthrough and the dashboard Role. The system-chart suite fails against the previous templates. ### Screenshots Not applicable: no dashboard change, only a new field in the Bucket form generated from the schema. ### Downstream repositories <!-- Cozystack is upstream for repositories that are NOT kept in sync with it automatically, and nothing in CI compares the two sides, so a change here can break them silently. Which change forces what, and which file to touch, is the trigger map in docs/agents/contributing.md under "Downstream Repositories". Walk it before you tick anything. IF YOU ARE AN AI AGENT OR AN LLM, THIS IS PART OF THE TASK, NOT A FORM TO FILL IN: 1. Walk the trigger map against the actual diff of this PR, file by file. Do not decide from the PR title or from your memory of what you changed. 2. For every repository you tick, open the follow-up PR there and link it on the same line. A ticked box with no link claims work that does not exist, which is worse than an empty box. Search that repository for an open PR or issue covering it first, and link that instead of filing a duplicate. 3. When the follow-up is out of scope, or needs a decision that is not yours to make, open an issue in that repository instead, link that, and say so in the PR body. Do not push a speculative PR into another repository just to fill a line here. 4. Do not tick "No downstream repository is affected" to make the checklist go away. If you are unsure, leave every box empty and say so in the PR body, so a human decides. --> Walked the trigger map against the diff. A new field in `packages/apps/bucket/values.schema.json` reaches the Terraform provider (schema, model, expand/flatten) and the website (the Bucket page is hand-written). Both follow-ups are issues rather than PRs, since they apply only once this PR is merged. - [ ] No downstream repository is affected by this change - [x] [cozystack/website](https://github.com/cozystack/website) - follow-up: cozystack/website#750 - [x] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: cozystack/terraform-provider-cozystack#71 - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note <!-- Write a release note: - Explain what has changed internally and for users. - Start with the same `type(scope):` prefix as in the PR title - Follow the guidelines at https://github.com/kubernetes/community/blob/master/contributors/guide/release-notes.md. --> ```release-note feat(bucket): add a `ui` flag to the Bucket application. Set it to `false` to skip the s3manager web UI and its Service, Ingress or HTTPRoute, DNS name and TLS certificate. Defaults to `true`, so existing buckets are unchanged. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added a `ui` option for bucket deployments. It is enabled by default and provides the S3 manager web UI at the tenant host. * Set `ui` to `false` to run a bucket without its web UI or the associated Service and Ingress or HTTPRoute. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
a3470391e2 |
fix(linstor): mark volumes restored from a snapshot DRBD-initialized (#4866)
## What this PR does Restoring a PVC from a LINSTOR VolumeSnapshot can leave one replica with an empty volume that DRBD marks UpToDate. A pod that lands on that replica sees an empty filesystem. linstor-csi restores the snapshot on one node and autoplaces the other replicas. LINSTOR v1.33.3 copies `Linstor/Drbd/InitialUptoDateOn` from the source volume into the restored volume definition and leaves the definition without `DRBD_INITIALIZED`. When autoplace puts a replica on the node that name points to, that empty new volume wins the initial UpToDate race, gets a random current UUID and a fresh filesystem, and goes StandAlone against the restored replica. LINBIT fixed this in v1.34.0. This PR backports that commit, LINBIT/linstor-server@9d8cdf5, to our v1.33.3 build as a patch. The README entry says to drop the patch with the move to v1.34.0 or later. Tested on a three-node cluster with a thick ZFS pool and `placementCount: 3`. Before the change the reproduction failed every time. With the patch I ran 5 restores, 4 of them with the source volume's winner on a different node than the restore. I also restored a snapshot taken before the change, and a 10Gi volume. Every time all replicas came up connected and UpToDate, a pod on each node read the same checksum, and the backing zvols were byte-identical when read with `O_DIRECT`. The resync after a restore moves about the written data, around 40 s for 1Gi and 134 s for 7.5 GiB on 10Gi. CSI clone PVC-to-PVC was checked too and is not affected. There is no e2e test. Every e2e lane runs without DRBD (`COZY_LINSTOR_DRBD_ENABLED=false`, StorageClass `local`), so a suite for replicated restores would never run in CI. Volumes restored before this fix are not repaired by it. How to find and fix them is in [this comment](https://github.com/cozystack/cozystack/issues/4862#issuecomment-6106661441). Known limitation, shared by upstream v1.34 since that code did not change: the autoplaced replicas skip the initial sync and rely on the source volume's day0 UUID still being in the restored replica's history. If that ever fails, DRBD goes StandAlone with "unrelated data" instead of syncing, which is visible, not silent. I could not reproduce it. Closes #4862 ### Screenshots Not a UI change. ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note fix(linstor): a PVC restored from a VolumeSnapshot no longer gets a replica with an empty volume marked UpToDate. Volumes restored before this release may still have such a replica; https://github.com/cozystack/cozystack/issues/4862#issuecomment-6106661441 explains how to check and repair them. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Restored snapshots with diskful DRBD resources are now recognized as initialized by default, helping them resume without unnecessary metadata recreation. * When force-initial-sync is enabled, restored volumes continue through the existing metadata-recreation path. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
d060c1dbb0 |
fix(kafka): pass the container limits to the Kafka JVMs (#4865)
## What this PR does The Kafka JVMs we ship size themselves from host memory instead of their container limits, and get OOMKilled. The Strimzi 0.45.1-rc1 images carry JDK 17.0.15, which reads `/proc/cgroups` to decide whether it runs in a container. Kernels 6.12 and newer built without `CONFIG_MEMCG_V1` no longer list the memory controller there, so the JVM turns container support off. The JDK fix is JDK-8347811, backported to 17.0.20 and 21.0.10. In CI this shows up in two places. The cluster operator gets a 25 GiB max heap inside its 512Mi limit. In 107 of the last 150 e2e reports the kernel OOM-killed a Java process at about 500M, the limit the cluster operator shares with the topic and user operators. Brokers and controllers start with a 5 GiB heap inside a 1Gi limit, because Strimzi asks the same JDK for the container memory and takes half of what it reports. This PR passes the limits to every Kafka JVM explicitly: - the cluster operator gets `-XX:MaxRAM` and `-XX:ActiveProcessorCount` from its own limits through the downward API; - brokers, controllers, the topic and user operators and the drain-time Cruise Control get `JAVA_TOOL_OPTIONS` with `-XX:MaxRAM` set to their memory limit, plus `-XX:ActiveProcessorCount` where the chart sets a CPU limit. The chart sets one only for brokers and controllers. A LimitRange default on the entity operators or Cruise Control is invisible to the chart, and Strimzi template env takes no `resourceFieldRef`, so those JVMs still count host CPUs. Every java in a container reads `JAVA_TOOL_OPTIONS`, including the heap probe Strimzi runs before starting Kafka. So Strimzi's own heap rules and Kafka's G1 defaults apply to the real memory limit, and the chart does no heap arithmetic. `jvmOptions` with `-XX` would not work here: Strimzi turns those into `KAFKA_JVM_PERFORMANCE_OPTS`, and Kafka skips its G1 settings when that is set. Each JVM now prints a "Picked up JAVA_TOOL_OPTIONS" line on start. In a kind cluster on such a kernel the operator then runs Serial GC with a heap of about 100 MiB, and peaks at 249Mi while creating a Kafka, against 440Mi before. A broker with a 1Gi limit and one CPU gets the same `-Xmx518982205` that Strimzi computes when the JDK sees the limit, with G1 and one concurrent GC thread. Existing Kafka clusters roll once on upgrade, Talos ones included, because the pod environment changes. Their heap does not change on a kernel where the JDK already sees the limit. The chart has no values key for JVM options or heap, so there is no user setting this could override. The Kafka migration hook now applies with `--openapi-patch=false`. Its container runs under a tenant LimitRange default of 128Mi, and a plain `kubectl apply` of an existing pool downloads the cluster's whole OpenAPI document, about 300Mi with the platform's CRDs, so every upgrade in such a tenant failed on an OOM-killed hook. With the flag kubectl builds the same merge patch from the last-applied annotation and peaks at about 35Mi. A larger memory limit would count against the tenant quota, and a server-side apply would stop removing fields that `kubectl create` set on the `kafka` pool. Other Jobs without resources are tracked in #4868. The operator OOMKill is what triggered the e2e failure in #4855. The other half is a Strimzi race. After a restart, the PodSet controller drops the ADD event of a PodSet that has no pods yet and only picks it up at the 5-minute resync. That one is upstream and is described in the issue. The other JVMs we ship are tracked in #4864. Talos nodes are not affected, the Talos kernel keeps `CONFIG_MEMCG_V1=y`. Generic-variant clusters on newer distribution kernels are. CI is affected even though it runs Talos, because there the Talos nodes are containers on the runner's Ubuntu 6.17 kernel. Closes #4855 ### Screenshots Not a UI change. ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note fix(kafka): the Strimzi cluster operator, Kafka brokers and controllers, the entity operators and the drain-time Cruise Control no longer size their JVM heap from host memory on kernels built without cgroup v1 memory support, which got them OOMKilled. The Kafka migration hook no longer runs out of memory on upgrade in a tenant with resource quotas. Existing Kafka clusters roll once on upgrade. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit - **New Features** - Kafka components now size JVM memory and processor settings based on their configured resource limits, including during migrations. - The Kafka cluster operator now receives container resource limits for JVM sizing. - **Bug Fixes** - Kafka migration operations avoid OpenAPI patch lookups that could use excessive memory. - **Tests** - Added coverage for JVM sizing, resource limits, and migration behavior. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
1f74ad4ee7 |
fix(multus): drop the CPU limit and make resources configurable (#4830)
<!-- Thank you for making a contribution! Here are some tips for you: - Use Conventional Commits for the PR title: `type(scope): description` - Types: feat, fix, docs, style, refactor, perf, test, build, ci, chore - Scopes are not an exhaustive list — pick the most specific scope for the change and extend the list when a genuinely new area appears. Examples: - System components: dashboard, platform, operator, cilium, kube-ovn, linstor, fluxcd, cluster-api - Managed apps: postgres, mariadb, redis, kafka, clickhouse, virtual-machine, kubernetes - Development and maintenance: api, hack, tests, ci, docs, maintenance - Breaking changes: append `!` after type/scope (`feat(api)!: ...`) or add a `BREAKING CHANGE:` footer - If it's a work in progress, consider creating this PR as a draft. - Don't hesistate to ask for opinion and review in the community chats, even if it's still a draft. - Add the label `kind/backport` if it's a bugfix that needs to be backported to a previous version. --> ## What this PR does The multus daemon was too small to recover a node after a CNI outage, and its limits could not be raised from values. The 100m CPU limit and the 1Gi memory limit of `kube-multus` were hardcoded in the patched upstream template. On a node with about 600 dead sandboxes and 220 pods waiting, multus was throttled in every CFS period. Its calls took longer than kubelet's two-minute CRI deadline, so every call was retried and the queue only grew. With the CPU limit lifted it OOM-looped at 1Gi. With 2 CPU and 4Gi it cleared the backlog in about three minutes. Now the resources come from a new `resources` value. The default keeps the same requests (100m CPU, 100Mi memory), has no CPU limit, and raises the memory limit to 4Gi. The memory limit stays on purpose. Without it the pod cgroup has no `memory.max`, and multus becomes a candidate for the Talos userspace OOM handler again. The chart now refuses to render when an override removes the memory limit or the memory request. Without a request Kubernetes uses the limit as the request, so a node with less allocatable memory than the limit would be left without multus. The change is in `patches/customize-deployment.patch`, so `make update` keeps it. I applied the patch to upstream v4.3.0 and got the committed template, except the image references. The platform reverts a direct edit of the child `cozystack.multus` Package, so a running cluster sets the value through the new `networking.multus.resources` key of the platform Package. The key is passed on only when set, and a value that is not a map stops the render. The system-defaults LimitRange in the namespace sets memory only, so it does not bring a CPU limit back. Closes #4829 ### Screenshots <!-- REQUIRED for UI changes: attach screenshots or screen recordings demonstrating the visual impact of your changes. PRs with UI changes without screenshots will not be merged. --> Not a UI change. ### Downstream repositories <!-- Cozystack is upstream for repositories that are NOT kept in sync with it automatically, and nothing in CI compares the two sides, so a change here can break them silently. Which change forces what, and which file to touch, is the trigger map in docs/agents/contributing.md under "Downstream Repositories". Walk it before you tick anything. IF YOU ARE AN AI AGENT OR AN LLM, THIS IS PART OF THE TASK, NOT A FORM TO FILL IN: 1. Walk the trigger map against the actual diff of this PR, file by file. Do not decide from the PR title or from your memory of what you changed. 2. For every repository you tick, open the follow-up PR there and link it on the same line. A ticked box with no link claims work that does not exist, which is worse than an empty box. Search that repository for an open PR or issue covering it first, and link that instead of filing a duplicate. 3. When the follow-up is out of scope, or needs a decision that is not yours to make, open an issue in that repository instead, link that, and say so in the PR body. Do not push a speculative PR into another repository just to fill a line here. 4. Do not tick "No downstream repository is affected" to make the checklist go away. If you are unsure, leave every box empty and say so in the PR body, so a human decides. --> - [ ] No downstream repository is affected by this change - [x] [cozystack/website](https://github.com/cozystack/website) - follow-up: https://github.com/cozystack/website/pull/747 - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: The diff adds a platform value, so the hand-written key table on the website needs it. The follow-up PR there is a draft until this one merges. ### Release note <!-- Write a release note: - Explain what has changed internally and for users. - Start with the same `type(scope):` prefix as in the PR title - Follow the guidelines at https://github.com/kubernetes/community/blob/master/contributors/guide/release-notes.md. --> ```release-note fix(multus): the kube-multus container no longer has a CPU limit, and its memory limit is raised from 1Gi to 4Gi, so a node with hundreds of pods can recover after a CNI outage. Its resources can be overridden through the new `networking.multus.resources` platform value. An override that removes the memory limit or the memory request now fails the render. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added optional CNI plugin staging during Multus startup, configurable through chart values. Staging skips when the plugin directory is unavailable and reports individual copy failures while continuing. * Made Multus resource settings configurable, with defaults of 100m CPU and 100Mi memory requests and a 4Gi memory limit. Rendering requires memory requests and limits. * Updated the Multus deployment to use the `cozy-multus` namespace and DaemonSet name, and Cilium as the master CNI configuration. * **Bug Fixes** * Added a 128Mi memory limit to the CNI installation step. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
fa9f09e3d8 |
fix(vm-disk)!: refuse a golden-image clone CDI would leave unbound (#4796)
## What this PR does A VM disk created from a golden image into a StorageClass other than the image's one can hang forever: its temporary clone PVC stays unbound, and the user sees nothing. With the default `csi-clone` strategy, CDI checks the source and target classes for a common provisioner, a matching volume mode and room to expand. It never compares class names. So a target class backed by the same provisioner gets no host-assisted fallback, and the clone is left to the CSI driver. LINSTOR creates it next to the source data, so on a target class that does not allow remote volume access from every node (a node-local class, for example) the PVC may never bind. The vm-disk chart now refuses such a disk at render time and tells the user which StorageClass to set. The check follows CDI's own clone planner. The effective strategy comes from the CDI override, or else from the target StorageProfile. It has to be `csi-clone`, or `snapshot` when CDI gets a VolumeSnapshotClass of the provisioner. Once the snapshot path has such a class it runs the same checks as csi-clone, and LINSTOR ships one. Both classes have to share a driver (the golden's is read from its PV, as CDI does), the volume modes have to match, and the target class has to allow expansion. On top of that the chart refuses only a LINSTOR target whose `allowRemoteVolumeAccess`, read the way linstor-csi reads it, is not true; without the parameter that means a layer list with no DRBD or NVMe layer. A remote-accessible LINSTOR class and other drivers render. When the provisioner or the volume mode differs, CDI falls back to a host-assisted copy, which completes, so the disk renders as before. A target class without expansion is left alone too, see the follow-ups. The class check compares nothing when a lookup it needs returns nothing: under `helm template`, before the golden PVC exists, or without the CDI resource. An empty `storageClass` is compared as the class CDI would pick for a kubevirt DataVolume, which is the default virt class, otherwise the Kubernetes default class. Existing disks are exempt, because their DataVolume spec is immutable. A disk counts as existing when its DataVolume or its PVC exists, since CDI can garbage-collect a completed DataVolume. Under `snapshot`, a snapshot class that both StorageProfiles name but that does not exist is refused too, for any driver, because CDI then fails to plan the clone instead of falling back. This is a breaking change: a new disk in a LINSTOR class without remote access from every node rendered before and is refused now, and so is one whose StorageProfiles name a snapshot class that does not exist. The first case can include a clone that would happen to work: on a class with `Immediate` binding, which I have not verified, or when the node the clone is placed on already holds a replica of the golden image. The way out is the golden image's class or the `copy` clone strategy. How this covers the three fix directions in the issue: 1. Omitting `cloneStrategyOverride` when it is empty already landed on main in #4138: the template skips the field for an empty or null value, the values schema accepts the empty string, and the chart tests pin both. This PR does not touch it. 2. I kept `csi-clone` as the default on purpose. Same-class clones are the common case, and `csi-clone` is the fast path for them. Changing the default is a separate decision, tracked in #4850. 3. vm-disk refuses the mismatch where the clone can hang, as described above. That is narrower than the issue proposed, which was to refuse every mismatch: every case CDI falls back on completes, and a clone into a remote-accessible LINSTOR class should complete too. The last part comes from reading the CDI and linstor-csi sources, I have not run it on a cluster. Follow-ups this PR does not cover: - When several classes claim the default, CDI picks the newest one. The chart does not reproduce that tie-break and compares nothing in that case. - The chart does not compare sizes. A target class without volume expansion is never refused for remote access, even when the disk is no larger than the golden image and CDI would attempt the clone. - Under `snapshot` on a cluster that does not serve the snapshot API, StorageProfiles naming a snapshot class still make CDI fail, and the chart does not look that class up. - A disk cloned from another disk (`source.disk`) into another class of the same provisioner can hang the same way, and nothing refuses it yet. - Whether `csi-clone` should remain the platform default now that it can be turned off: #4850. Closes #2908 ### Screenshots Not a UI change. ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: No values, schema or ApplicationDefinition change. Re-check notes for the next CDI and linstor-csi bumps sit next to the version pins in the kubevirt-cdi-operator and linstor Makefiles. The new note in the vm-disk README reaches the website through the regular reference-page regeneration. ### Release note ```release-note fix(vm-disk)!: a new disk from a golden image is now refused with a clear error when CDI would CSI-clone it into another LINSTOR StorageClass that does not allow remote volume access from every node. Before, such a disk could stay pending forever with no error. A clone that would have landed on a node already holding a replica of the golden image is refused as well; use the golden image's StorageClass or the copy clone strategy. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Prevented image-backed disks from being rendered when CDI’s selected clone strategy cannot safely clone across differing storage classes, including applicable LINSTOR remote-access and snapshot-class checks. * Existing DataVolumes and same-namespace PVCs are not blocked by these checks. Disk creation can proceed when required information is unavailable or the selected strategy supports the operation. * **Documentation** * Clarified when image-backed disks may be refused and recommended using the golden image’s storage class or the copy strategy as alternatives. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
785cbc391b |
fix(fluxcd): keep Helm uninstall working during flux-plunger recovery (#4293)
## What this PR does Fixes #4060. `flux-plunger` recovers a HelmRelease stuck with `has no deployed releases` by briefly suspending it, deleting the stale Helm storage Secret, recording a processed-version annotation, and unsuspending. helm-controller v1.5.x skips the Helm uninstall and drops its finalizer when it handles a delete on a suspended HelmRelease, and it wakes on the same delete event flux-plunger does, so a delete arriving inside that window orphaned every resource the release owns (for a VMDisk: DataVolume, PVCs, the CDI importer pod, RBAC, WorkloadMonitor and the storage Secret itself). Lifting the suspension on the delete event cannot win that race reliably. The bug is not specific to VMDisk. The change makes such a delete reach the uninstall: - **An uninstall fence.** The suspension is applied together with a flux-plunger finalizer, `flux-plunger.cozystack.io/uninstall-fence`, in one server-side apply, so flux-plunger never holds a suspension without it. If a delete arrives while the release is suspended, the fence keeps the object whether helm-controller or flux-plunger handles the delete first: flux-plunger lifts its suspension and keeps the fence, helm-controller reconciles the unsuspended generation and runs the uninstall, and flux-plunger removes the fence once helm-controller's finalizer is gone and it has observed that generation. A recovery that completes lifts the suspension and the fence together. A terminating HelmRelease never begins recovery, and termination is re-checked immediately before deleting the storage Secret. - **Only flux-plunger's own suspension is acted on.** Ownership is decided by which field manager owns `spec.suspend` in `metadata.managedFields`: the apiserver transfers the field away the moment an operator (or `cozyhr resume`, or a backup/restore controller) writes a different value to it, so a later suspension is never misread as flux-plunger's. A suspension set through the shared `flux-client-side-apply` manager (platform migrations, the tenant delete hook, an operator's manual `kubectl apply`) is never claimed. A release deleted under another manager's suspension is that manager's decision: flux-plunger does not hold it with the fence, and helm-controller leaves its resources in place, as the migrations that suspend and then delete rely on. - **No suspension taken over in a race.** Acquiring applies without forcing first and, on a conflict, re-fetches and forces only if `spec.suspend` is still `false`: a backup controller owns the field at `false` via a dynamic-client `Update`, which a non-forced apply can never take. Every apply flux-plunger sends, acquiring as well as lifting the suspension or the fence, is preconditioned on the `resourceVersion` and `uid` of the read that decided on it. The `resourceVersion` makes a write landing in between fail the apply instead of being absorbed: acquire then defers rather than adopt or take over a suspension set meanwhile, and lifting the suspension and the fence from a release read as live cannot delete it without an uninstall if helm-controller has handled a delete in the meantime. The `uid` stops an apply to a release that has gone from creating an empty one, since server-side apply creates what does not exist. A conflict is retried through the requeue. The apply carries only `spec.suspend` and the fence, so it cannot leak the required `spec.interval` and conflict on it. - **Fresh reads.** The release, every re-check and the storage Secret list are read from the apiserver (an uncached `APIReader`), not the informer cache. A lagging cache would let the processed-version guard delete the revision below the one just reclaimed, and the ClusterRole grants secrets `get`/`list` but not `watch`, which an informer needs to stay synced; flux-plunger deliberately does not cache Secrets. Every step requeues with backoff on failure. - **Events.** A Warning when flux-plunger holds a suspension it failed to clear, and a Warning when a delete has been held by the fence for more than ten minutes waiting for helm-controller (the held state is re-checked on a timer, not only on helm-controller's next status write). A release deleted under another manager's suspension gets a Normal event when that is a migration's choice, and a Warning when the release carries flux-plunger's processed-version annotation, because then the skipped uninstall is an accident, not a decision. Normal events also mark an externally-owned suspension left alone and a recovery deferred because the release changed between read and write; an external suspension on a release flux-plunger has recovered before is a Warning instead, because it is most likely one an earlier flux-plunger left mid-recovery (see Operating notes). Events from the shutdown drain are written straight to the apiserver, since the manager's recorder stops with the manager. - **The fence is released when flux-plunger goes.** Once its manager has stopped, and with it every reconcile, flux-plunger drains its fences under a deadline inside the pod's termination grace period; a stop that overran its 10s bound is drained too and still reported: a recovery in progress is aborted, the suspension and the fence lifted together for the next flux-plunger to start again, and a release being deleted has flux-plunger's suspension lifted and keeps the fence until helm-controller has run its uninstall. A release helm-controller does not handle in time keeps its fence. The drain lives in the controller, so the envtest suites hold it against a real apiserver's generations and finalizers. A pre-delete hook on the chart is the backstop for what the drain could not finish, so uninstalling the component never leaves a release it cannot finish deleting: it stops flux-plunger, waits out its grace period, then lifts any remaining suspension and fence without waiting again, naming each release it lets go of before helm-controller uninstalled it. It lifts a suspension only where flux-plunger alone holds it, the outcome the controller's own relinquish has, with a JSON patch of `spec.suspend` preconditioned on the `resourceVersion` and `uid` it read; not with `kubectl apply --server-side`, which on a release last written by a client-side `kubectl apply` moves that apply's fields to the applying manager and strips every one the body leaves out. helm-controller runs a pre-delete hook under the release's uninstall timeout, 300s by default and not set by the operator, so the Job's deadline sits under it. A Deployment that cannot be stopped or a listing that never succeeds ends the hook before any fence is touched, and a fence it cannot remove ends it after the sweep; either way it exits non-zero, because a failed pre-delete hook leaves the release untouched and helm-controller retries the uninstall, hook included, whereas exiting 0 would let the component go and strand the fence. A flux-plunger pod still there after its grace period, typically one stuck `Terminating` on a `NotReady` node, is only reported, and the pod wait is cut to what is left of the hook's retry window; because such a pod may still be setting fences, the fences are listed again after the sweep and any found fails the hook. The Job runs once and is kept after success so its report stays readable until its TTL; `helm.sh/hook-output-log-policy` is deliberately not used, because helm-controller never sets Helm's hook output writer and calls a nil one for it (fluxcd/helm-controller#1562). The hook's kubectl image is digest-pinned in the chart values, and its RBAC is only what `kubectl scale`, the listing and the patches issue. The chart's README documents the finalizer and how to clear it by hand. A single writer is kept by leader election, not by the rollout. A second process acting under the same field manager could clear a suspension the first is still recovering, and no Deployment strategy prevents one: the next pod starts as soon as the old one is terminating (Kubernetes v1.35 has no pod-replacement policy for Deployments), and an eviction or a node drain replaces a pod the same way, while the old one stops and drains. The chart now passes `--leader-elect` with a Role on `leases` in the release namespace. The Lease is not given up on stop and outlasts the last renewal, the renew deadline, the manager's bounded stop (10s) and the drain, and only a flux-plunger that led drains at all, so the next one acts only once the old one is done; the price is that a new pod waits for the Lease to run out, a little under two minutes at the default. The timings derive from one value, `shutdownGracePeriodSeconds` (90 by default, refused outside 40 to 140 at render): the pod's termination grace period, the drain deadline (25s less: the manager's 10s stop plus a 15s margin before the kubelet's SIGKILL, both tied to the Go constants by a contract test) and the hook's pod wait. The strategy keeps `maxSurge: 0` and `maxUnavailable: 1` and stays `RollingUpdate` rather than `Recreate` on purpose: the chart shipped without a strategy block, so every existing install's live Deployment carries the apiserver-defaulted `rollingUpdate` object and helm-controller applies server-side, where laying `type: Recreate` over that populated block is rejected on upgrade. ### Operating notes A HelmRelease carries the fence only while flux-plunger is recovering it or waiting for helm-controller to uninstall it. A fenced release whose uninstall keeps failing stays `Terminating` exactly as any HelmRelease does under helm-controller's own finalizer, and raises the Warning above. Stopping flux-plunger drains its fences, and uninstalling it releases whatever the drain left through the pre-delete hook; a fenced release that is deleted while flux-plunger is merely scaled to zero, or killed without a graceful stop, and that helm-controller has not uninstalled, stays `Terminating` until flux-plunger runs again. To release one by hand, after confirming its uninstall has run or is not wanted: ```bash kubectl patch helmrelease NAME --namespace NAMESPACE --type json --patch '[{"op":"test","path":"/metadata/finalizers/INDEX","value":"flux-plunger.cozystack.io/uninstall-fence"},{"op":"remove","path":"/metadata/finalizers/INDEX"}]' ``` where `INDEX` is the position of `flux-plunger.cozystack.io/uninstall-fence` in `metadata.finalizers`; the `test` operation makes the patch fail rather than remove another finalizer if the list has changed. Earlier flux-plunger releases set `spec.suspend` through the shared `flux-client-side-apply` manager, so a suspension one of them left behind cannot be told apart from a migration's or an operator's and is treated as external: it is not cleared automatically. Such a leftover exists only if the old pod stopped in the middle of a recovery, and flux-plunger raises a `SuspensionNotOwned` Warning on it. The chart README carries this section too. To list candidates, suspended releases carrying the flux-plunger annotation whose `spec.suspend` is not owned by flux-plunger's apply: ```bash kubectl get helmreleases.helm.toolkit.fluxcd.io --all-namespaces --output json | jq --raw-output '.items[] | select(.spec.suspend == true) | select(.metadata.annotations["flux-plunger.cozystack.io/last-processed-version"] != null) | select([.metadata.managedFields[]? | select(.manager == "flux-plunger" and .operation == "Apply" and .fieldsV1["f:spec"]["f:suspend"] != null)] | length == 0) | "\(.metadata.namespace)/\(.metadata.name)"' ``` Clearing one is an operator action: confirm nothing else (a migration, a restore) is holding it, then resume it with `flux resume helmrelease NAME --namespace NAMESPACE`. ### Testing The regression the issue asks for is `TestEnvtest_DeleteDuringRecoveryReachesUninstall`: against a real apiserver, a delete lands while flux-plunger holds its recovery suspension, and helm-controller's v1.5.0 delete handling is reproduced step for step (uninstall only when not suspended, finalizer dropped either way, observed generation recorded). It covers both orders, helm-controller handling the delete first and flux-plunger handling it first; without the fence the first order leaves the release gone with no uninstall. The same suite pins the managedFields ownership dynamics a fake client cannot represent: the field transfer, the forced acquire over a dynamic-`Update` owner, the `resourceVersion` precondition rejecting a write that races either apply, the boundary that a `flux-client-side-apply` suspension is never claimed, and interval preservation. The fence mechanics were also checked against a live helm-controller: with another finalizer holding a deleted, suspended release, lifting the suspension made helm-controller run the uninstall and remove the release's resources. The envtest suite runs on every pull request: a new `make test-controllers-envtest` target builds a pinned `setup-envtest` and fetches a kube-apiserver and etcd into `_out/envtest`, which CI caches and the target reuses without asking the release index, takes the HelmRelease CRD from the in-tree Flux manifests, and CI calls it next to `make test-controllers`; the control plane gets a longer start timeout because it starts beside the other test goals. The drain is held there too: it aborts a live recovery, carries a delete through the uninstall and lifts the fence only once helm-controller has observed the unsuspended generation, keeps the fence when helm-controller never answers, releases a fence left without a suspension at once, and leaves another manager's suspension alone. `TestEnvtest_TheNextFluxPlungerLeadsOnlyAfterTheDrain` runs two real managers on one Lease: a clean stop still drains, and the second manager becomes leader only after the first one's drain has ended; it goes red if the Lease is given up on stop. Unit tests cover the controller logic (every branch, ordering, requeue, and the ownership decision through an injected seam), the Lease timing relations, that only a leader drains and through the manager's API reader rather than its stopped cache, that a failed listing is retried, that a stop which overran its grace period is still drained and its events reach the apiserver, and contract tests tie `main.go`, the chart's flags, the drain's arithmetic and the hook's names to the Go code. The pre-delete hook is covered by helm-unittest and by `hack/flux-plunger-fence-hook_test.bats`, which runs its rendered script against a fake `kubectl` that keeps each release's finalizers, suspension owner, generation and observed generation, bumps the generation on a spec write as the apiserver does, answers NotFound without `--ignore-not-found`, spends simulated time on waits, lists a release once however many copies of the fence it carries, refuses `kubectl apply`, lifts a suspension only through the preconditioned JSON patch and never one another manager also holds, reads a negative `kubectl wait` timeout as a week as kubectl does, and applies a finalizer removal only when it is the guarded test-then-remove at an index that holds the fence. Every mutation in a set covering each predicate conjunct, each retry, each exit path, the re-listing, the timings and the selector turns the hook suite red, as does every mutation in the Go set covering the drain's branches, the Lease timings and the events; three drain mutations that still survive are tracked in #4782. The hook script was also run as a Job in the hook's own image on a live cluster, succeeding, with the Deployment already gone, and with patch denied by RBAC, where it exited non-zero and named the release it left; that run caught that a per-call `--request-timeout` makes kubectl drop its in-cluster config, so the hook sets none and the fake rejects it. A later live run caught `kubectl apply --server-side` stripping the finalizers and spec of a release created by a client-side apply; with the JSON patch the same releases kept every field, the suspension flux-plunger alone held was lifted, a co-owned and a foreign one stayed, and every fence went. ### Remaining limitations - A delete that arrives after recovery has deleted the storage Secret of a release whose only revision was that one finds no revision to uninstall; helm-controller then treats the release as already gone. - A writer that sets `spec.suspend: true` while flux-plunger already holds it at `true` does not take the field over, because the value does not change. If such a writer then deletes the release inside the recovery window (the suspend-then-delete that the tenant delete hook and some platform migrations use to skip the uninstall), flux-plunger still sees its own suspension, lifts it, and helm-controller runs the uninstall that writer meant to skip. The same held before this change, when the end of recovery unsuspended unconditionally. - The already-processed guard compares revision numbers only. When Helm re-creates a revision under the same number after recovery deleted it (a release whose only revision fails again the same way), recovery runs again for it. - `listHelmReleaseSecrets` reads the local cluster only, so a HelmRelease that targets a remote cluster via `spec.kubeConfig` (whose storage Secrets live in the remote cluster) is not recovered; it is skipped, never mis-handled. - A new flux-plunger pod waits for the old one's Lease to run out before it acts, on every restart and after a crash: a little under two minutes at the default. Recovery is not latency-sensitive, and this is what keeps a single writer while the old pod drains. - The leader Lease is left in the release namespace after the chart is uninstalled, as with any controller-runtime leader election; it is inert. ### Screenshots Not applicable: no UI change. ### Downstream repositories The trigger map was walked against the diff: it touches `internal/controller/fluxplunger`, `cmd/flux-plunger`, the `packages/system/flux-plunger` chart (templates including RBAC for the leader Lease, a pre-delete hook, values, tests, its package `Makefile`, README), a new bats test under `hack/`, the root `Makefile` (a new `test-controllers-envtest` target; existing targets are unchanged) and the pull-request workflow that calls it and caches its binaries. No row matches: ccp gates on existing `hack/` files and make targets, and nothing there is moved, renamed or changed in behaviour; a new test file and a new target reach none of them. The website's FluxPlunger section describes the recovery steps, which still hold; it does not describe the fence or the drain, which the chart README now documents. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note fix(fluxcd): a HelmRelease deleted while flux-plunger is recovering it now reaches the Helm uninstall instead of leaving its resources (DataVolume, PVCs, RBAC, storage Secret) behind ``` |
||
|
Mattia Eleuteri
|
0c62bee4da |
feat(bucket): add a ui flag to skip the s3manager web UI
Every bucket ships an s3manager Deployment with its Service and an Ingress or HTTPRoute on <bucket>.<tenant host>. Tenants that only use the S3 API pay for a pod per bucket and for one DNS name and TLS certificate per bucket, none of which they need. ui defaults to true, so existing buckets keep their UI. With ui set to false the bucket no longer needs the tenant apex either, since the UI hostname was its only consumer in the bucket-system chart. Assisted-by: LLM Signed-off-by: Mattia Eleuteri <mattia@hidora.io> |
||
|
Aleksei Sviridkin
|
7c46ffff12 |
fix(backupstrategy-controller): run backup clients on a package-owned image (#4756)
## What this PR does The Altinity (ClickHouse) and RabbitMQ backup strategy Pods ran `platform-migrations`: a 349 MB image carrying `kubectl`, `helm`, `git`, `cozyhr` and `etcd-migrate`, whose `ENTRYPOINT` is `run-migrations.sh`. Both pins were stamped from `packages/core/platform/Makefile`, so any migration change re-digested the backup clients too, and only the `command:` override kept the Pods from running platform migrations (#3420). - New `packages/system/backupstrategy-controller/images/backup-http-client/`: `alpine:3.24` (digest-pinned, the same base the tree already uses) + `curl` + `jq` + `ca-certificates`, `USER 65532:65532`, no `ENTRYPOINT`. Everything is installed at build time, so the Pods still never run `apk add` and keep working air-gapped. - New `image-backup-http-client` target in the package's own `Makefile`, chained after `image-redis-backup` like the existing ones so only one `yq -i` writes `values.yaml` at a time. It stamps `chBackupClientImage` and `rabbitmqBackupClientImage` with the same ref. - Removed the cross-package stamps from `packages/core/platform/Makefile`, the WORKAROUND/TODO comments in the chart and the RabbitMQ example, and the stale "live violation" line in `docs/agents/image-refs.md`. - `hack/image-pin-consistency.bats`: dropped the `platform-migrations`-specific test, whose subject no longer exists. The general check (no repository pinned at more than one digest, computed from `hack/promote-retag.sh --dry-run`) still covers the two keys sharing one image. **Why one image for both strategies rather than `ch-backup-client` as the issue named it.** The RabbitMQ strategy had the same reuse and the same cross-package stamp; leaving it would have kept the stamp alive. Its script needs `curl --aws-sigv4` + `ca-certificates`, a subset of the ClickHouse one, so one image serves both. The two values keys stay separate so either strategy can move to its own image later. **Initial pin.** The image does not exist in ghcr until CI builds it, so both keys are committed as `backup-http-client:v1.6.0` without a digest, the same way `redis-backup` was introduced. PR CI rebuilds touched packages and overlays the fresh refs for e2e; release preparation's `make image` stamps tag+digest. Image size: 6.9 MB vs 349 MB. Verified locally: - `docker buildx build` for `linux/amd64,linux/arm64`; in the image as uid 65532: curl 8.22 with `--aws-sigv4`, jq 1.8.2, `date`, `seq`, writes to `/tmp` (the RabbitMQ script's only write), TLS verification against the bundled CA store. - `helm unittest` (23/23), `helm template` renders both strategies with `backup-http-client` and no `platform-migrations` reference. - `hack/cozytest.sh hack/image-pin-consistency.bats` and `hack/build-matrix_test.bats` pass. Not yet run end to end on a cluster; the e2e backup round-trips will exercise it. Fixes #3420 ### Screenshots N/A — no UI changes. ### Downstream repositories Walked the trigger map against the diff: it touches `packages/system/backupstrategy-controller` (new image, Makefile target, values comments/pins, template comments), `packages/core/platform/Makefile` (stamp removal only, no `values.yaml` key change), `hack/image-pin-consistency.bats`, `docs/agents/image-refs.md` and a comment in `examples/backups/rabbitmq`. No app package, schema, CRD, variant, asset, platform values key or `hack/package.mk` change. The website does not list first-party image repositories (searched for `platform-migrations` and `redis-backup`), so no mirror list needs the new one. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note <!-- Write a release note: - Explain what has changed internally and for users. - Start with the same `type(scope):` prefix as in the PR title - Follow the guidelines at https://github.com/kubernetes/community/blob/master/contributors/guide/release-notes.md. --> ```release-note fix(backupstrategy-controller): the ClickHouse (Altinity) and RabbitMQ backup strategy Pods now run a dedicated `backup-http-client` image (alpine + curl + jq + ca-certificates, non-root, ~7 MB) instead of the 349 MB `platform-migrations` image. Air-gapped mirrors need the new `ghcr.io/cozystack/cozystack/backup-http-client` repository. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Improvements** * Altinity and RabbitMQ backups now use a dedicated backup HTTP client image, configured separately from the platform migrations image. * The client image includes the tools required for backup operations and runs with a non-root identity. * Both backup configurations receive the same digest-pinned image reference when the image is built. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Andrey Kolkov
|
647407545d |
fix(backupstrategy-controller): run backup clients on a package-owned image
The Altinity and RabbitMQ strategy Pods ran platform-migrations, a 349 MB image carrying kubectl, helm and etcd-migrate whose ENTRYPOINT is the migration runner, and whose pins were stamped from packages/core/platform so every migration change moved the backup clients too. Build images/backup-http-client (alpine + curl + jq + ca-certificates, non-root) from this package's Makefile and stamp both client keys from it. The cross-package stamp in packages/core/platform/Makefile and the platform-migrations-specific check in hack/image-pin-consistency.bats go away; the general one-digest-per-repository check still covers the two keys sharing one image. Fixes #3420 Assisted-by: LLM Signed-off-by: Andrey Kolkov <androndo@gmail.com> |
||
|
Yasar Rahman
|
8be7fb2e66 |
feat(redis): expose min-replicas-to-write and min-replicas-max-lag
Lets an operator bound the writes lost when an isolated Redis master is failed over: the master refuses writes while fewer replicas than configured are connected and recent. Both values are unset by default, so the rendered Redis config is unchanged. Redis treats 0 in either directive as disabling the check, so the chart refuses minReplicasMaxLag 0 next to a replica requirement instead of silently turning the protection off. Negative values are refused by the schema (minimum 0), since Redis rejects them at CONFIG SET and the operator would stop healing the Sentinels of that instance. A requirement of replicas or more is refused at render: a master with replicas pods has replicas-1 replicas, so it would refuse every write for good. Assisted-by: LLM Signed-off-by: Yasar Rahman <yasar.rehman@gmail.com> |
||
|
Aleksei Sviridkin
|
33ca8b67bb |
feat(redis): run Sentinel on the same image as the Redis pods (#4831)
## What this PR does
The Redis application pins its Sentinels to `redis:6.2.6-alpine`
(`packages/apps/redis/templates/redisfailover.yaml`), while the data
pods run the version selected by `version` (`redis:8.4.0` for `v8`,
`redis:7.4.7` for `v7`). The pin was added in
|
||
|
Aleksei Sviridkin
|
76a4af95c0 |
docs(monitoring): correct the release name the OIDC comment, guide and test fixture encode (#3468)
## What this PR does

The Grafana OIDC `clientId`, audience-scope name, client-secret name and
users-Job name are all derived from the Monitoring release name. In a
running cluster that release is always `monitoring-system`: the tenant
chart's outer HelmRelease `monitoring` points at `extra/monitoring`,
whose `templates/helmrelease.yaml` creates the inner HelmRelease `{{
.Release.Name }}-system` that carries `system/monitoring` and renders
OIDC. There is no release named `monitoring` that renders OIDC.

Three places encoded a release named `monitoring` (i.e.
`<ns>-monitoring`, where a cluster renders `<ns>-monitoring-system`),
per #3338:

- `packages/system/monitoring/templates/_helpers.tpl` header comment —
both example lines were wrong. The per-tenant release is
`monitoring-system`, and the platform Grafana lives in the `tenant-root`
namespace, not `cozy-monitoring`. (`cozy-monitoring` only hosts the
ExternalName services that redirect to the platform stack the root
tenant hosts in `tenant-root` — see
`packages/system/cozystack-basics/templates/monitoring-external-services.yaml`.)
- `docs/oidc-grafana.md` — placed the platform release in
`cozy-monitoring`; it lives in `tenant-root`. It also named the
per-tenant release `monitoring`; that is `monitoring-system` too, so
both instances now read `monitoring-system` and differ only by
namespace.
- `packages/system/monitoring/tests/oidc_test.yaml` — the suite pinned
`release.name: monitoring`, so its clientId / audience-scope /
client-secret / users-Job assertions pinned names no cluster renders.
Both fixtures are set to `monitoring-system` and the derived expected
values updated to what a cluster actually renders.

Nothing changes at runtime — the templates are self-consistent whatever
the release is called; this only aligns the descriptions and the test
fixture with reality.

Out of scope here (from the issue, left for a maintainer decision):
- Confirming/removing the apparently-dead `cozystack.monitoring`
PackageSource in `packages/core/platform/sources/monitoring.yaml` (issue
item 3) — removing a source is a call I can't safely make.
- Re-checking Detail B of #3259 against the corrected topology (issue
item 4).

Verification, rebased on current main: `helm unittest -f
'tests/oidc_test.yaml' packages/system/monitoring` — 39/39 pass; the
whole monitoring chart passes as well. After setting the fixtures I
updated only the assertions helm-unittest reported as newly diverging.

Disclosure: prepared with AI assistance; I reviewed the change and
verified the release-name topology against the source files cited above.

### Screenshots

N/A — no UI changes.

### Downstream repositories

Walked the trigger map in `docs/agents/contributing.md` against the
diff, file by file. The three changed paths are a `system/monitoring`
chart `_helpers.tpl` comment, the repo-internal `docs/oidc-grafana.md`,
and a chart test fixture. None match a listed trigger: no change under
`packages/apps/` or `packages/extra/`, no
`packages/core/platform/values.yaml`, and no
variant/bundle/component/release-asset/Talos/tooling change. So no
downstream repository is mechanically affected. (The website's own OIDC
page referenced in cozystack/website#597 is a separate artifact the
reporter is already engaged with, outside this repo's trigger map.)

- [x] No downstream repository is affected by this change

### Release note

```release-note
docs(monitoring): correct the release name (`monitoring-system`) and platform namespace (`tenant-root`) encoded in the Grafana OIDC helper comment, the OIDC guide, and the chart test fixture.
```


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->

## Summary by CodeRabbit

- **Documentation**
- Clarified that both platform and tenant Grafana instances use the
`monitoring-system` release name. The platform instance runs in
`tenant-root`, while tenant instances run in their respective tenant
namespaces.
- Updated the OIDC integration guidance to reflect the platform
namespace and tenant release naming.

<!-- end of auto-generated comment: release notes by coderabbit.ai -->
|
||
|
Aleksei Sviridkin
|
4295930989 |
feat(dashboard): show categories brought by tapped repositories in the sidebars (#4741)
## What this PR does The marketplace and console sidebars render a fixed category list, `["IaaS", "PaaS", "NaaS"]`, and drop every other `spec.dashboard.category`. A repository tapped with `cozypkg` that brings its own category is reachable only at the bottom of the full application list, and its installed applications get no console section at all. Both sidebars now follow `groupByCategory`, the order the marketplace page already uses: IaaS, PaaS, NaaS first, then any other category alphabetically. `Administration` stays in the Admin portal, as before. Unknown categories get the generic grid icon. The note in `docs/agents/contributing.md` that described the hardcoded list is removed, since it no longer holds. Tests: two new cases in `sidebar-sections.test.tsx` (a tapped `Paleocomputing` category appears after the built-in ones in both sidebars, `Administration` stays out). Both fail on the previous code. The console suite (448 tests), `pnpm typecheck` and `eslint` on the changed files pass. ### Screenshots Same cluster and tenant, a repository tapped that brings the `Paleocomputing` category. Before, marketplace: the category is only reachable at the bottom of the full list. 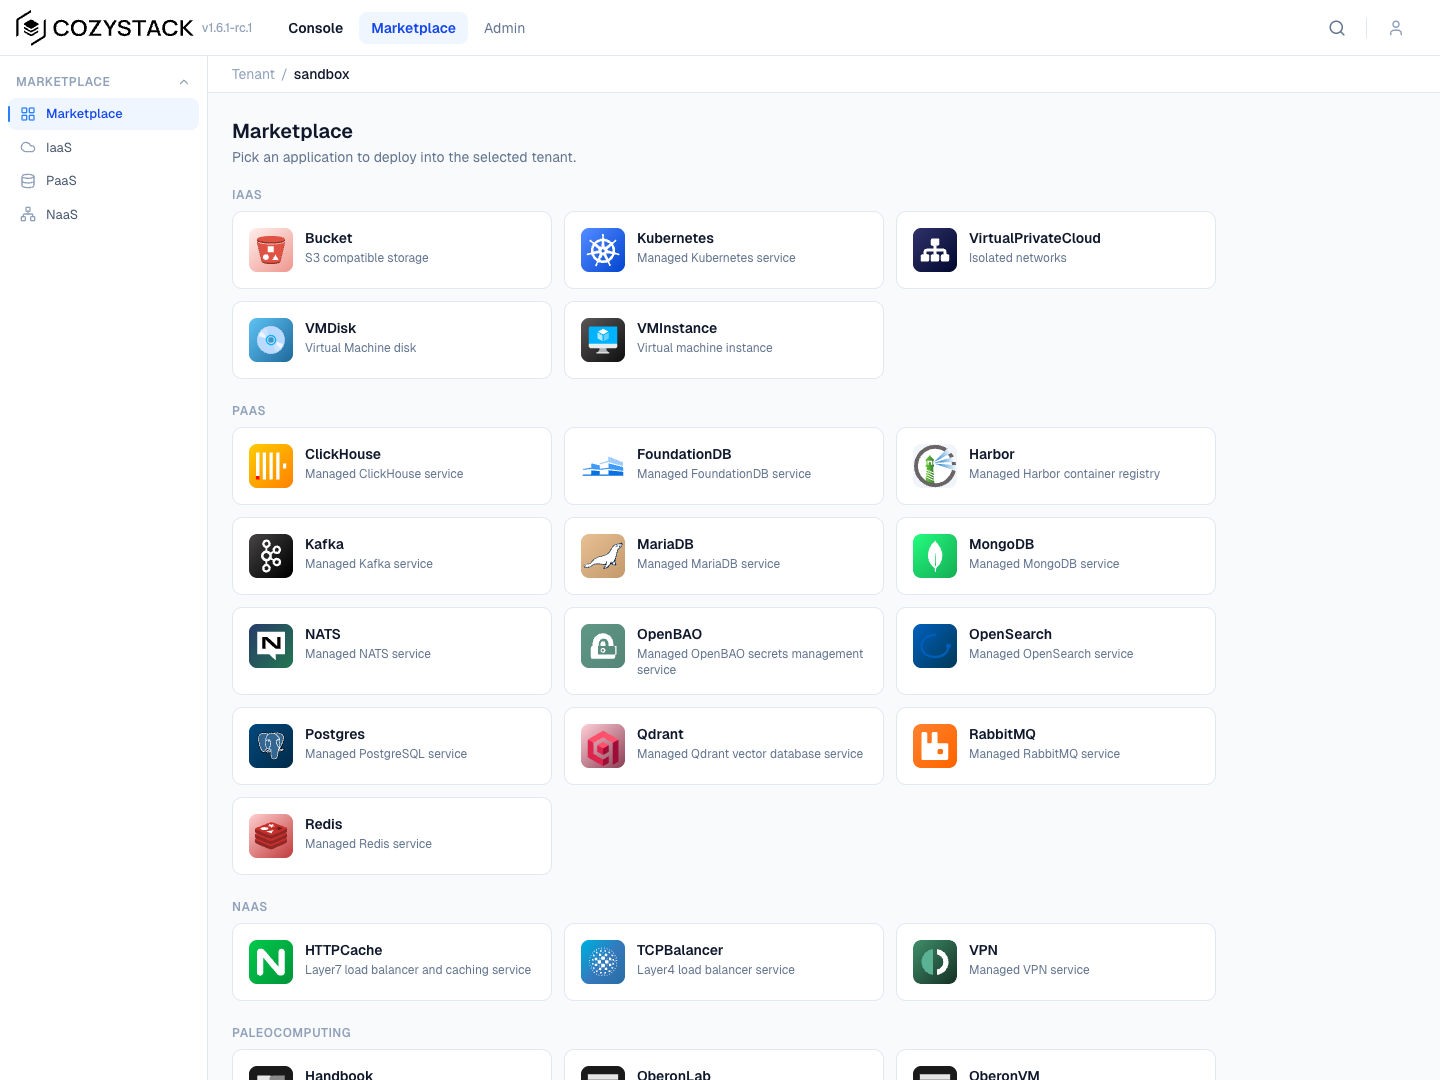 After, marketplace: the category gets its own filter. 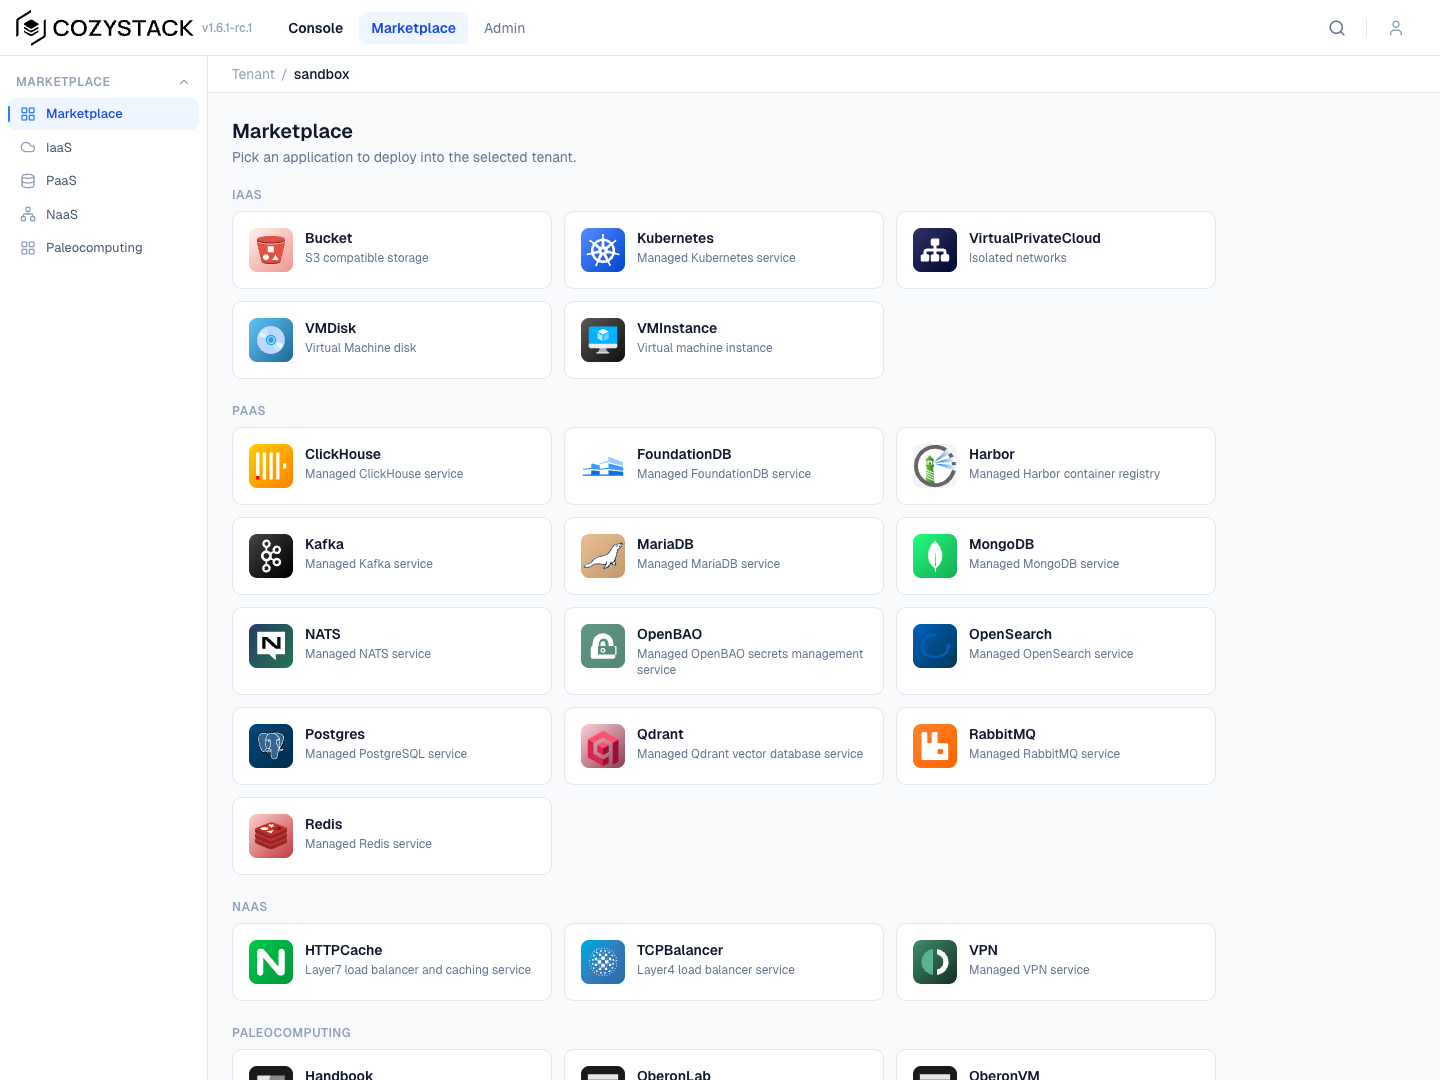 Before, console: no section for the tapped applications. 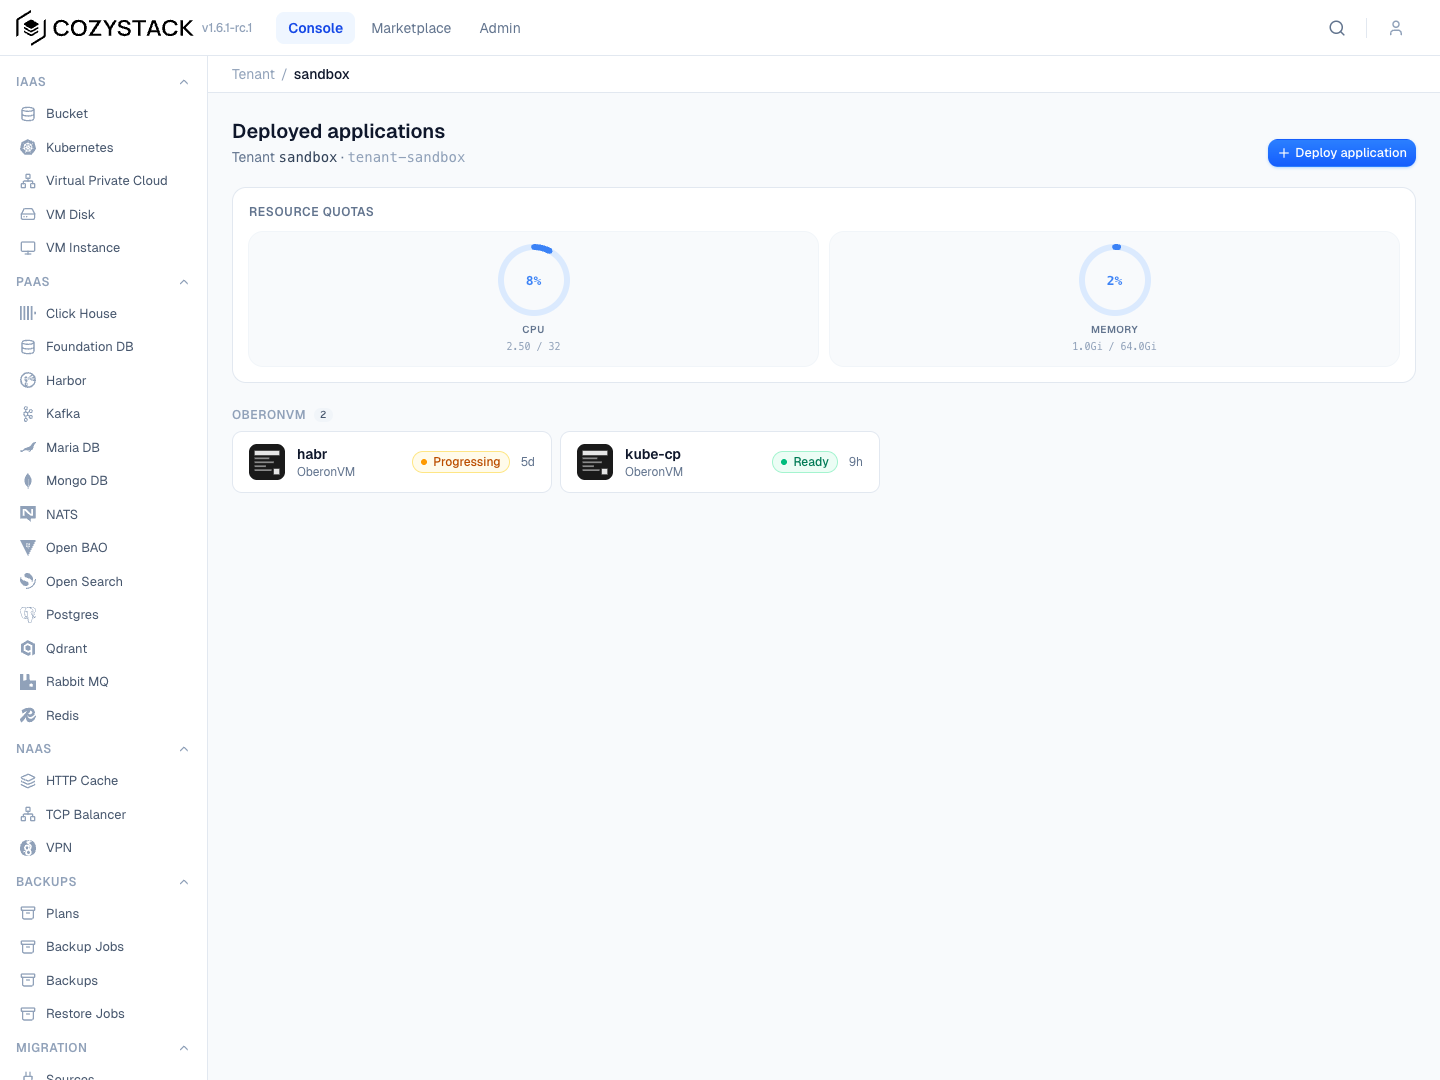 After, console: installed applications of that category get their own section. 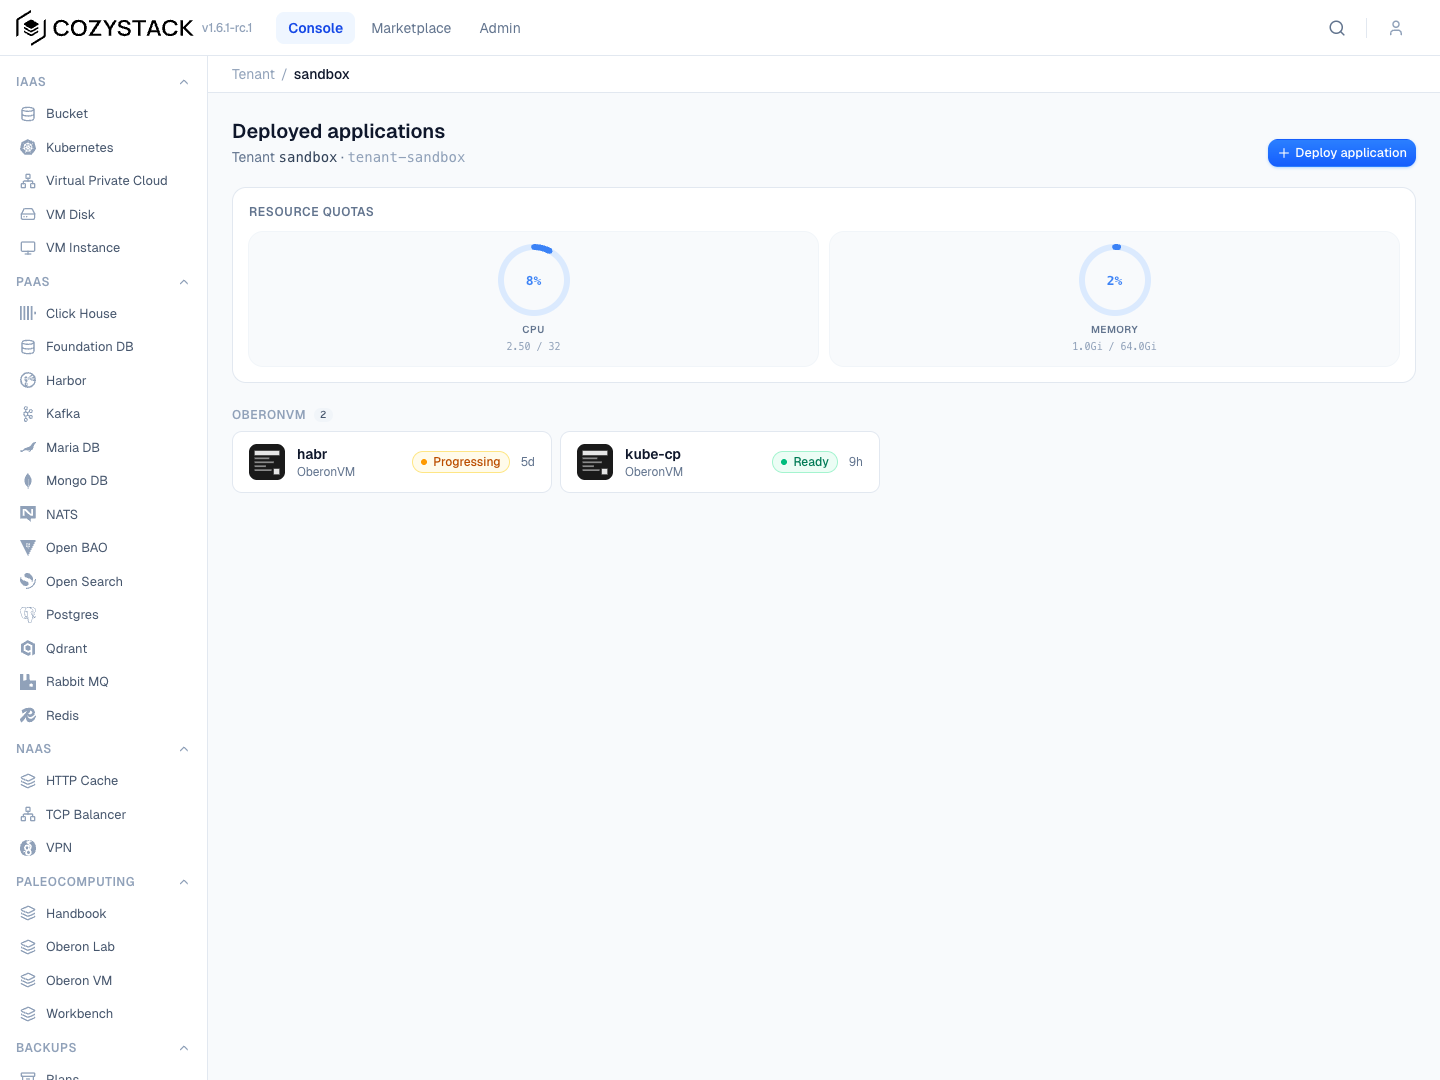 ### Downstream repositories Walked the trigger map against the diff: it touches only the console sidebar code and a note in `docs/agents/contributing.md`. No package, values schema, CRD, installer value or `ApplicationDefinition` field changes. The website page on `ApplicationDefinition` does not restrict `spec.dashboard.category` values, and `external-apps-example` uses `PaaS`, which keeps working as before. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note feat(dashboard): categories brought by tapped repositories now appear in the marketplace and console sidebars, after IaaS, PaaS and NaaS, instead of only in the full application list. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Marketplace and Console sidebars now show application categories beyond the built-in options, including custom categories. Categories appear in the order provided by the application grouping. * The Administration category remains excluded from both sidebars. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
youdie006
|
b7708fb285 |
docs(monitoring): correct the release name the OIDC comment, guide and test fixture encode
The naming block in _helpers.tpl, the guide's opening paragraph and the oidc test fixture all describe the per-tenant Grafana as the release `monitoring`. Both instances are released as `monitoring-system` by the monitoring application and differ only by namespace: the platform one in `tenant-root`, a per-tenant one in each tenant namespace. Assisted-by: LLM Signed-off-by: youdie006 <youdie006@users.noreply.github.com> |
||
|
Aleksei Sviridkin
|
b255dc4dd8 |
fix(kafka-operator): size the operator JVM from its container limits
The JDK 17 in the Strimzi 0.45.1-rc1 operator image decides whether to read the container limits by looking at /proc/cgroups. Kernels 6.12 and newer built without CONFIG_MEMCG_V1 no longer list the memory controller there, so the JVM turns container support off and takes host RAM and host CPUs as its budget: on a 128 GiB node it picks G1 with a 25 GiB max heap and a 2 GiB initial heap inside a 512Mi limit, and the kernel OOM-kills the operator under load. A restart at the wrong moment leaves a freshly created StrimziPodSet without pods for up to the five-minute informer resync, which is how a KRaft controller pool ends up never starting within an e2e timeout. The limits now reach the JVM through the downward API as -XX:MaxRAM and -XX:ActiveProcessorCount, so they follow any later change to the container resources. In a test cluster the operator then picks Serial GC and a heap of about 100 MiB. The upstream JDK fix is JDK-8347811, backported to 17.0.20 and 21.0.10. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Yasar Rahman
|
9a88afe6ca |
feat(redis): run Sentinel on the same image as the Redis pods
The Sentinels were left on redis:6.2.6-alpine when the operator moved to the freshworks-oss fork, so that its new compiled-in default could not move them on upgrade. 6.2 is end of life, and every instance now runs a Sentinel one or two major versions behind the Redis it monitors. The rollback risk behind that pin, a newer engine rewriting dump.rdb in a format the older one cannot load, does not apply to Sentinel. It stores no RDB or AOF, only sentinel.conf on an emptyDir that the config-copy init container rewrites from the operator's ConfigMap on every start, so moving back to an older image starts from a clean config. Taking the image from the same version map as the data pods also means one image per node instead of two. The e2e comment that relied on busybox's timeout exit code in the Sentinel container is updated, since that container now carries coreutils. Signed-off-by: Yasar Rahman <yasar.rehman@gmail.com> Assisted-by: LLM |
||
|
Aleksei Sviridkin
|
e5689e2a63 |
fix(linstor): mark volumes restored from a snapshot DRBD-initialized
linstor-csi restores a snapshot on one node and autoplaces the other replicas. In LINSTOR v1.33.3 the restored volume definition has no DRBD_INITIALIZED flag, so the initial UpToDate race is still open, and Linstor/Drbd/InitialUptoDateOn, copied from the source volume through the snapshot, names the node that won it for the source. When a replica is autoplaced on that node, the empty new volume wins the race: it gets a random current UUID and a fresh filesystem, and goes StandAlone against the restored replica. A pod attached there sees an empty volume. Backport the upstream fix, released in LINSTOR v1.34.0, which sets the flag on a restore unless the resource definition asks for new metadata through ForceInitialSyncPermanent, as a backup does. Nothing wins the race any more, and an autoplaced replica resyncs from the restored one like any replica added to an existing volume. Link: https://github.com/LINBIT/linstor-server/commit/9d8cdf5118338fc72a34bb99799e452e031ea8f6 Closes: #4862 Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
df2e1c33e1 |
feat(kubernetes-nodes): build the Proxmox worker template from the pool's Talos values (#4742)
## What this PR does
A `substrate: proxmox` pool clones its workers from a VM template the
chart never sees: capmox selects it by `proxmox.templateTags`, and the
pool's `talos.*` values reach only the installer written into the worker
machineconfig. Nothing in the repository says which image that template
has to carry, and the image an operator reaches for is the wrong one:
- The release asset `nocloud-amd64.raw.xz` is built from
`packages/core/talos/images/talos/profiles/nocloud.yaml`, the bare-metal
node image. Its `zfs` extension starts `ext-zfs-service`, which waits
for `/dev/zfs`. A VM never has it, so `startAllServices` never finishes,
and Talos fails the boot sequence and reboots the guest each time the
boot timeout runs out. On our v1.13.6 stand that was every ~70 minutes,
visible in the tenant only as `SandboxChanged` on every Pod (218 cilium
restarts in 12 days); from the Proxmox side the VM never restarts. The
same profile also follows the host nodes' Talos (v1.14.2 since
|
||
|
Andrei Kvapil
|
05cfb63044 |
feat(keycloak): expose zone placement for Keycloak and the database proxy (#4606)
## What this PR does Neither the Keycloak StatefulSet nor the `keycloak-kms-proxy` Deployment exposes any placement, so the scheduler is free to put both replicas of each in one failure domain. For Keycloak this is worse than it looks: a StatefulSet does not replace a pod stuck on an unreachable node, so losing that domain takes every Keycloak replica with it for as long as the domain stays lost. This exposes placement for both, with empty defaults so nothing changes unless an installation opts in: - `affinity` and `topologySpreadConstraints` for the Keycloak StatefulSet; - `encryption.affinity` and `encryption.topologySpreadConstraints` for the proxy; - a `PodDisruptionBudget` (`maxUnavailable: 1`) for the proxy when `encryption.replicas > 1`, so a drain cannot take both replicas at once. The `values.yaml` example spreads one replica per zone with `whenUnsatisfiable: DoNotSchedule` and `nodeTaintsPolicy: Honor`. The taint policy matters for a zone loss: kube-scheduler already ignores terminating pods when it counts the spread (`countPodsMatchSelector` in `pkg/scheduler/framework/plugins/podtopologyspread/common.go`, "Bypass terminating Pod"), but with the default `nodeTaintsPolicy: Ignore` the lost zone's nodes still count as a domain holding zero pods, so a replacement pod could not be placed on the surviving zone without violating `maxSkew`. With `Honor`, nodes carrying the `node.kubernetes.io/unreachable` NoSchedule taint drop out of the count and the replacement schedules. `ScheduleAnyway` was tried first in a live deployment and did not spread the proxy replicas on rollout. Found during a site-isolation drill in which both Keycloak pods and both proxy replicas had drifted into one zone. Tests: new `tests/placement_test.yaml` (defaults render no placement; set values render as given; PDB only for more than one proxy replica); `helm unittest` passes 87/87; the default render is unchanged apart from a randomly generated secret. ### Screenshots Not applicable, no UI changes. ### Downstream repositories Walked the trigger map in `docs/agents/contributing.md` against the diff: it touches only `packages/system/keycloak` (templates, values, tests) — no app under `packages/apps` or `packages/extra`, no platform values, CRD, `hack/` tooling, commit convention or PR template. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note feat(keycloak): expose affinity and topologySpreadConstraints for Keycloak and the keycloak-kms-proxy, and add a PodDisruptionBudget for the proxy when it runs more than one replica. Defaults are unchanged. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added optional node affinity and topology spread settings for Keycloak, its KMS proxy, and the database to control pod placement. * Database-specific topology spread settings take precedence over cluster-wide settings; constraints without a selector are scoped to the database cluster. * Added a disruption budget for the KMS proxy when running multiple replicas, allowing up to one pod to be unavailable. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
f093273736 |
feat(redis): size the Sentinel pods separately from Redis (#4832)
## What this PR does

The Redis application renders `spec.sentinel.resources` from the same
`resources`/`resourcesPreset` pair as the Redis pods. Every instance
runs three Sentinels, so it reserves three extra copies of a Redis
replica's memory for processes that hold only their configuration and
the failover state. The dataset that drives the Redis sizing never
reaches a Sentinel.

On our Cozystack v1.6.4 staging cluster, an HA Redis on `t1.nano`
reserves 3 x 128Mi for its Sentinels. The VPA recommender
(recommendation mode only) gives an uncapped target of 16Mi for the
`sentinel` container. On a `u1.small` instance the same three Sentinels
would reserve 3 x 4Gi.

This PR adds an optional `sentinel` block with the same two keys the top
level has:

```yaml
resourcesPreset: u1.small
sentinel:
  resources:
    cpu: 100m
    memory: 64Mi
  # resourcesPreset: t1.nano
```

Resolution rules:

- `sentinel` empty (the default): the Sentinels keep the Redis sizing
(`resources` + `resourcesPreset`). Existing instances therefore render
exactly as before and an upgrade does not roll their Sentinels.
- `sentinel.resourcesPreset` set: the Sentinels use that preset.
Explicit top-level `resources` are not carried over, since they were
sized for the dataset.
- `sentinel.resources` set: it wins. Any key it leaves out is filled
from `sentinel.resourcesPreset`, which falls back to `resourcesPreset`.
- The Sentinel `WorkloadMonitor` label
`workloads.cozystack.io/resource-preset` now carries the preset the
Sentinels actually use. The Redis `WorkloadMonitor` is unchanged.

Changes:

- `values.yaml`: new `Sentinel parameters` section (`@typedef Sentinel`,
`@param {Sentinel} [sentinel]`, default `{}`), reusing the existing
`Resources` and `ResourcesPreset` types so the enum and quantity
validation is the same as the top-level pair.
- `templates/redisfailover.yaml`: computes the Sentinel preset and
resources once and uses them for `spec.sentinel.resources` and the
Sentinel `WorkloadMonitor` label.
- `README.md`: generated table rows plus a short hand-written `sentinel`
section next to `resources and resourcesPreset`.
- Generated: `values.schema.json`, `api/apps/v1alpha1/redis/types.go`
(new `Sentinel` struct, `ConfigSpec.Sentinel`),
`api/apps/v1alpha1/redis/zz_generated.deepcopy.go`,
`packages/system/redis-rd/cozyrds/redis.yaml`.
- `tests/sentinel_resources_test.yaml`: 10 helm-unittest cases covering
the rules above and an unknown preset being refused.

I chose not to change the default sizing. A smaller default (for example
a fixed small preset for Sentinel) would save more for everyone, but it
would also roll every instance's Sentinels and change what tenants are
billed for on upgrade. If maintainers prefer that, it is a one-line
follow-up on top of this change.

Testing done:

- `make generate` in `packages/apps/redis` with cozyvalues-gen v1.7.0
(the version `pre-commit.yml` installs); regenerated files committed.
- Deepcopy: `controller-gen object` v0.16.4 on `api/apps/v1alpha1` (the
last step of `hack/update-codegen.sh`), only the redis package changed;
`go build ./...` and `go vet ./redis/` pass in that module, `go mod
tidy` leaves no diff. I could not run the full root `make generate` on
my machine: code-generator v0.37.1 fails to parse the Go 1.27.1 standard
library (`math/rand/v2: method must have no type parameters`), which is
a host toolchain problem unrelated to this change. CI's `codegen-drift`
job should confirm.
- `make test` in `packages/apps/redis` (helm-unittest v1.1.2): 58
passed. With the template change reverted, 4 of the new cases fail (the
ones that set `sentinel.*`); the cases that pin today's behaviour pass
both ways.
- Rendered output with no `sentinel` block is identical to `main` (all
documents except the random-password Secret) for the defaults,
`resourcesPreset=u1.small`, and explicit `resources` (cpu 1, memory
2Gi).

Backwards compatibility: purely additive. The field is optional with an
empty default, existing instances render unchanged, and nothing rolls on
upgrade. Clients that do not know the field are unaffected.

### Screenshots

Not a UI change. The dashboard form gets a `sentinel` object from the
schema like other nested parameters (e.g. `tls`).

### Downstream repositories

- [ ] No downstream repository is affected by this change
- [ ] [cozystack/website](https://github.com/cozystack/website) -
follow-up:
- [ ]
[cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack)
- follow-up:
- [ ]
[cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack)
- follow-up:
- [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up:
- [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up:
- [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) -
follow-up:
- [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) -
follow-up:
- [ ]
[cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server)
- follow-up:
- [ ]
[cozystack/external-apps-example](https://github.com/cozystack/external-apps-example)
- follow-up:
- [ ] [cozystack/examples](https://github.com/cozystack/examples) -
follow-up:
- [ ] [cozystack/community](https://github.com/cozystack/community) -
follow-up:

Trigger map walked against the diff: this adds a field to
`values.schema.json`, so `cozystack/terraform-provider-cozystack` needs
to model `sentinel.resources` / `sentinel.resourcesPreset` in its Redis
resource. I will open that issue once this PR has a number and link it
here; a draft is in `FOLLOWUP-terraform-provider-redis-sentinel.md`. The
website page for `redis` is regenerated from `README.md` by the release
bot (`redis` is in the website `APPS` list), so no manual follow-up
there. Nothing else in the map is touched.

### Release note

```release-note
feat(redis): new optional `sentinel.resources` and `sentinel.resourcesPreset` parameters size the three Sentinel pods independently of the Redis pods. When unset, Sentinels keep the Redis sizing as before, so existing instances are unchanged.
```


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Added independent CPU and memory resource settings and sizing presets
for Redis Sentinel pods.
* When Sentinel-specific settings aren’t provided, Sentinel pods inherit
Redis resource settings. Unspecified Sentinel resource values can use
the Sentinel preset, which defaults to the Redis preset.
* Added configuration documentation and validation for Sentinel resource
settings.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->
|
||
|
Marian Koreniuk
|
bbd39c94a4 |
feat(kubernetes-nodes): build the Proxmox worker template from the pool's Talos values
A proxmox pool clones its workers from a VM template the chart never sees, and nothing said which Talos image that template has to carry. The one an operator reaches for, the platform release's nocloud-amd64.raw.xz, is the bare-metal node image: its zfs extension's service waits for a /dev/zfs no VM has, the boot sequence never completes, and Talos reboots every worker each time the boot timeout runs out, about every 70 minutes on v1.13. It also follows the host nodes' Talos version, not the pool's talos.version that the installer in the worker machineconfig names. The chart's default schematic has a trap of its own: its qemu-guest-agent service waits the same way for the agent's virtio port, which Proxmox adds only to a VM with the agent enabled. hack/proxmox-talos-template.sh builds the template from the chart's talos.schematicID and talos.version in the nocloud flavour with the agent enabled, refuses a tag set another template already carries, because capmox then finds two and clones neither, and prints the templateTags that select it. Assisted-by: LLM Signed-off-by: Marian Koreniuk <moriarti@cp.if.ua> |
||
|
Aleksei Sviridkin
|
08ee470f6a |
fix(postgres)!: refuse plaintext sessions on external instances (#4847)
## What this PR does CloudNativePG offers TLS on an external Postgres but does not require it. Its built-in last `pg_hba` rule is `host all all all`, which matches TLS and non-TLS connections alike, so a client outside the cluster that connects with `sslmode=disable` gets an unencrypted session. The chart's `tls.enabled` only decides whether the external hostname goes into the certificate, so it cannot prevent this. This is #4619. When `external: true`, the chart now renders `spec.postgresql.pg_hba`: ```yaml pg_hba: - hostssl all all all scram-sha-256 # md5 on PostgreSQL 13, matching CloudNativePG's default rule - host all all all reject ``` CloudNativePG puts user rules after its fixed rules (`local` peer, `streaming_replica` and pooler `cert`) and before its default `host all all all` rule, and PostgreSQL uses the first matching rule, so the two lines above make remote sessions TLS-only without touching replication or the metrics exporter. See the CloudNativePG [`pg_hba` section](https://cloudnative-pg.io/documentation/current/postgresql_conf/#the-pg_hba-section) and the [template](https://github.com/cloudnative-pg/cloudnative-pg/blob/v1.30.0/pkg/postgres/configuration.go) for v1.30.0, the operator version the platform ships. A new tri-state `tls.required` follows the same pattern as `tls.enabled`: when omitted it follows `external`, `false` opts out, `true` requires TLS on an in-cluster instance too. The issue is silent on a switch; I added one because the change is breaking and a tenant with a client that cannot do TLS needs a way back that does not mean patching the operator's resources. In-cluster clients: the pod network cannot be told apart from an external client (the external Service uses `externalTrafficPolicy: Local`, so the source IP is the client's), so the rules apply to every remote client. The chart's init job connects to `<release>-rw` with libpq's default `sslmode=prefer`, which already negotiates TLS, as do the backup and monitoring paths that run inside the pod over the Unix socket. Only clients that disable TLS explicitly are refused. In-cluster instances with `external: false` are unchanged. Changes: - `templates/_tls.tpl`: `postgres.tls.required` helper. - `templates/db.yaml`: renders `spec.postgresql.pg_hba` when required. - `values.yaml`: `tls.required`, with the generated `values.schema.json`, `README.md`, `api/apps/v1alpha1/postgresql/types.go` and `packages/system/postgres-rd/cozyrds/postgres.yaml`. The `Required` deepcopy block in `zz_generated.deepcopy.go` is controller-gen v0.16.4 output. - `README.md`: new "Refusing plaintext sessions" paragraph. - `tests/pg_hba_test.yaml`: 10 helm-unittest cases. Backwards compatibility: breaking for existing external instances whose clients connect without TLS. The rules apply on the next reconcile. They are refused until the client enables TLS or the instance sets `tls.required: false`. Testing done: - `make generate` in `packages/apps/postgres` with cozyvalues-gen v1.7.0; regenerated files committed. - `helm unittest .` in `packages/apps/postgres`: 206 passed (25 suites), 10 of them new. I did not run it against a live cluster, so the `pg_hba` ordering is taken from the operator source and docs rather than observed. ### Screenshots Not a UI change. The dashboard form gets a `tls.required` toggle from the schema. ### Downstream repositories I walked the trigger map against the diff and left every box empty so a human decides. The nearest hit is the website's managed-apps reference page for postgres, which a stable-tag bot regenerates from `README.md`; the Terraform provider's postgres schema may also want the new `tls.required` field. - [ ] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note fix(postgres)!: an external Postgres now refuses sessions that are not encrypted. The chart renders `hostssl` rules for all users and databases with scram-sha-256 (md5 on PostgreSQL 13, matching CloudNativePG's default rule) and rejects plain `host` connections, so a client using `sslmode=disable` is refused. The new `tls.required` value follows `external` by default; set it to `false` to keep accepting plaintext sessions. ``` Fixes #4619 <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added a `tls.required` setting for PostgreSQL instances. By default, TLS is required for external instances and optional for others. You can override this behavior to require encrypted connections for both external and in-cluster clients, or allow plaintext connections for external instances. Rendering fails if TLS is required while PostgreSQL SSL is disabled. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
f0e3e17493 |
feat(kubernetes-nodes): let CDI trust a self-hosted Talos image factory (#3797)
## What this PR does Adds `talos.imageFactoryCA` to the `kubernetes-nodes` chart, so CDI can verify a Talos Image Factory served with a certificate from an internal CA. Fixes #3796. ### The gap `talos.imageFactoryURL` is documented for self-hosted factories and mirrors in air-gapped, rate-limited or flaky-egress environments. Such an endpoint is normally served by the organisation's own CA, and CDI, which trusts only its system store, refuses the import with `x509: certificate signed by unknown authority`. The DataVolume never completes and no worker joins. `DataVolume.spec.source.http.certConfigMap` exists for exactly this, but the worker DataVolume in `templates/nodegroup.yaml` renders `url` alone and no value reaches that field. ### The change One optional value on the existing `talos` group of a `KubernetesNodes` pool: ```yaml talos: imageFactoryURL: "https://factory.example.com" imageFactoryCA: | -----BEGIN CERTIFICATE----- ... -----END CERTIFICATE----- ``` When set on an HTTP import path (the default and `osImage.factory`), the chart renders a ConfigMap `<release>-talos-factory-ca` in the release namespace and points the DataVolume's `source.http.certConfigMap` at it. A pool on `osImage.builtin` clones a golden image, builds no HTTP source and gets no ConfigMap. Empty, the default, renders nothing: `helm template` with the field unset is byte-identical to `main`, so existing pools keep their KubevirtMachineTemplate name. Setting the CA changes that name, so the pool rolls once. CDI appends the bundle to the system pool rather than replacing it (`x509.SystemCertPool()` followed by `AppendCertsFromPEM` in `pkg/importer/http-datasource.go`), so a publicly trusted endpoint keeps verifying. The PEM is taken inline rather than as a ConfigMap name because `certConfigMap` must live in the DataVolume's namespace, and the dashboard offers no way to create that object by hand. ### Fail-closed guards The value lands verbatim in a ConfigMap that anything able to read the namespace can read, so it must be complete PEM certificate blocks and nothing else, and must never carry private key material. That includes the realistic accident of `cat ca.pem key.pem` pasted into the field. The rules now live in one shared helper, `cozy-lib.tls.validateCACert`, which `cozy-lib.tls.caCertSecret` also calls instead of keeping its own copy. The regexes are unchanged; the failure message names the caller's field. ### Testing - `packages/apps/kubernetes-nodes/tests/talos_image_factory_ca_test.yaml`, 13 cases: unset renders nothing, set renders the ConfigMap and a matching `certConfigMap`, whitespace-only counts as unset, multi-certificate chains, the builtin path, and each guard on the input that trips it. - `packages/tests/cozy-lib-tests/tests/tls_validatecacert_test.yaml`, 6 cases for the shared helper, plus the existing `caCertSecret` tests updated for the new message. - `make generate` in the package: regenerated `values.schema.json`, `README.md`, `api/apps/v1alpha1/kubernetesnodes/types.go` and the `kubernetes-nodes-rd` definition are committed. Not yet exercised end to end against a live internal factory. ### Not in this PR `packages/apps/vm-disk/templates/dv.yaml` renders `source.http.url` with the same gap. Left for a follow-up if this shape is accepted. ### Screenshots Not a UI change. ### Downstream repositories - [ ] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [x] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: cozystack/terraform-provider-cozystack#31 (the field belongs to the `kubernetes_nodes` model) - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: Walked the trigger map against the diff: - **terraform-provider-cozystack**: ticked. The diff adds a field to `packages/apps/kubernetes-nodes/values.schema.json`, which the trigger map names directly. Filed as an issue there. - **website**: not ticked. No package is added, renamed or removed, and the reference page is regenerated from the package `README.md`, which is regenerated and committed here. - Every other repository: no path in the trigger map is touched. ### Release note ```release-note feat(kubernetes-nodes): add `talos.imageFactoryCA` so CDI can verify a self-hosted Talos Image Factory served with a certificate from an internal CA. Previously the worker image import failed with `x509: certificate signed by unknown authority`. Set the CA in PEM form and the chart wires it into the worker DataVolume; leave it empty and nothing changes. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added an optional setting for providing PEM certificate authorities trusted when importing worker OS images over HTTPS. This supports the default image source and factory images, allowing imports from endpoints that use certificates not already trusted by the system. * Certificate authorities are provided as PEM certificate blocks; when configured, they are used for HTTPS image imports. The setting defaults to empty and has no effect on pools using built-in OS images. * **Bug Fixes** * Invalid certificate input, including private keys, is rejected. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Andrei Kvapil
|
dde75d6cf5 |
feat(keycloak): expose zone placement for the keycloak-db instances
The Keycloak StatefulSet and the database proxy can already be spread across failure domains, but the CloudNativePG Cluster behind them could only follow the cluster-wide topology constraint, with no way to pick zones for this database alone. With both instances in one zone, losing that zone loses the database and every login with it. Add database.affinity (CloudNativePG shape) and database.topologySpreadConstraints, with empty defaults so nothing changes unless an installation opts in. The cnpg.io/cluster label selector is added to constraints that carry none, and the constraints replace the cluster-wide ones for this database when set. Assisted-by: LLM Signed-off-by: Andrei Kvapil <kvapss@gmail.com> |
||
|
Aleksei Sviridkin
|
faf8a250ba |
fix: typo in monitoring-agents values.yaml (#4799)
<!-- Thank you for making a contribution! Here are some tips for you: - Use Conventional Commits for the PR title: `type(scope): description` - Types: feat, fix, docs, style, refactor, perf, test, build, ci, chore - Scopes are not an exhaustive list — pick the most specific scope for the change and extend the list when a genuinely new area appears. Examples: - System components: dashboard, platform, operator, cilium, kube-ovn, linstor, fluxcd, cluster-api - Managed apps: postgres, mariadb, redis, kafka, clickhouse, virtual-machine, kubernetes - Development and maintenance: api, hack, tests, ci, docs, maintenance - Breaking changes: append `!` after type/scope (`feat(api)!: ...`) or add a `BREAKING CHANGE:` footer - If it's a work in progress, consider creating this PR as a draft. - Don't hesistate to ask for opinion and review in the community chats, even if it's still a draft. - Add the label `kind/backport` if it's a bugfix that needs to be backported to a previous version. --> ## What this PR does Fixes a typo in monitoring-agents values.yaml. ### Screenshots <!-- REQUIRED for UI changes: attach screenshots or screen recordings demonstrating the visual impact of your changes. PRs with UI changes without screenshots will not be merged. --> ### Downstream repositories <!-- Cozystack is upstream for repositories that are NOT kept in sync with it automatically, and nothing in CI compares the two sides, so a change here can break them silently. Which change forces what, and which file to touch, is the trigger map in docs/agents/contributing.md under "Downstream Repositories". Walk it before you tick anything. IF YOU ARE AN AI AGENT OR AN LLM, THIS IS PART OF THE TASK, NOT A FORM TO FILL IN: 1. Walk the trigger map against the actual diff of this PR, file by file. Do not decide from the PR title or from your memory of what you changed. 2. For every repository you tick, open the follow-up PR there and link it on the same line. A ticked box with no link claims work that does not exist, which is worse than an empty box. Search that repository for an open PR or issue covering it first, and link that instead of filing a duplicate. 3. When the follow-up is out of scope, or needs a decision that is not yours to make, open an issue in that repository instead, link that, and say so in the PR body. Do not push a speculative PR into another repository just to fill a line here. 4. Do not tick "No downstream repository is affected" to make the checklist go away. If you are unsure, leave every box empty and say so in the PR body, so a human decides. --> - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note <!-- Write a release note: - Explain what has changed internally and for users. - Start with the same `type(scope):` prefix as in the PR title - Follow the guidelines at https://github.com/kubernetes/community/blob/master/contributors/guide/release-notes.md. --> ```release-note ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Corrected the namespace metadata field used for event streams. Event metadata is now labeled consistently, helping downstream tools identify the namespace associated with each event. This fixes an incorrect field name in the event output configuration without changing other event stream behavior. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
bcde187858 |
fix(dashboard): small Console fixes from the #3828 triage (#3837)
## What this PR does Six small Console fixes from the #3828 triage. Each one is small and most of the code sits in `apps/console/src`, so they go together in one PR. `Fixes #3105`: sizes between 1Ki and 1Mi printed as a raw byte count. `humanizeBytes` had branches for Ti, Gi and Mi and then fell through to bytes. It now has a Ki branch with the same `toFixed(0)` as the Mi branch. The `1023B` case still holds, and the test covers 1Ki and 512Ki. `Fixes #3106`: the tenant picker showed on admin pages where the tenant changes nothing. It is now hidden on the cluster-scoped admin pages only: Capacity, Backup classes, External IPs and Modules. The rest of `/admin` mounts the same tenant-scoped pages as `/console`, and those take their namespace from the tenant context, so the picker stays there. `/admin/tenants` keeps it too, because its rows come from the picker-filtered tenant list. `Fixes #3107`: both capacity drill-downs showed one generic error, so a permission failure looked like a broken page. Both now use the `error instanceof K8sApiError && error.status === 403` check that `ClusterStorageSection` already uses, with a test for the forbidden case and one for a generic error on each page. `Fixes #3102`: an immutable leaf was not restored when the YAML edit dropped its parent object. `overlayPath` stopped as soon as the submitted body had nothing at a path segment. It now creates `{}` for the missing parent, but only when the target there is undefined or null and the original really has the leaf to restore. So a scalar or an explicit null the user put there survives. A wildcard with more path under it does not rebuild a deleted parent, since that would put back entries the user removed. The test uses foundationdb's `storage.storageClass`, which is a shipped path of this shape. `Fixes #3135`: a blocked submit did not scroll to the field that blocked it. Plain `focusOnFirstError` crashes here, because RJSF's built-in handler reads `form.elements` and this form is `tagName="div"`. So the form passes a small handler that finds the field by its generated id and scrolls it into view. The ids come from one shared definition, and the widgets that had none now carry it: the `DynamicOptionsWidget` select, which every `x-cozystack-options` field uses, and the `SourceField` controls. The nested form that `AdditionalPropertiesField` mounts per map entry continues the outer id namespace instead of restarting at `root`, so fields like `nodeGroups.*.instanceType` resolve. A map key with a dot in it, such as a mariadb user `john.doe`, resolves by trying both readings of the dotted error path. `Fixes #3108`: `cilium`, `coredns` and `verticalPodAutoscaler` have only `valuesOverride` and no `enabled`, so they rendered as plain groups next to the toggleable addons and looked like a switch that failed to appear. Setting `<addon>.enabled: true` in the YAML editor is accepted, because the schema sets no `additionalProperties`, and the API stores the field and echoes it back. Nothing reads it. The three addons are not the same case. `cilium` and `coredns` are always installed. `verticalPodAutoscaler` has no switch of its own and is installed and removed together with `addons.monitoringAgents.enabled`. The three are now marked in `values.yaml` with a new `x-cozystack-no-enable-switch` schema keyword, and the form renders them with a note that there is no enable switch and an `enabled` field in YAML does nothing. The per-addon reason goes into the schema description, which the form renders and which regenerates into the README, the Go types and the ApplicationDefinition. The generated files are regenerated with cozyvalues-gen v1.7.0, the version CI pins, and the pre-commit check passes. The console typecheck and tests pass in CI. ### Screenshots ##### Ki formatting <img width="1182" height="184" alt="image" src="https://github.com/user-attachments/assets/62662265-4f77-455d-b90e-85e417684bb9" /> ##### Admin without tenant picker <img width="1440" height="245" alt="image" src="https://github.com/user-attachments/assets/99aff4f3-fda9-4c4c-8cf8-0c1eb01fb973" /> ##### Capacity 403 error <img width="1232" height="270" alt="image" src="https://github.com/user-attachments/assets/f4e4b328-ee5e-4516-b78f-9b5084b6bbc8" /> <img width="1232" height="944" alt="image" src="https://github.com/user-attachments/assets/142e438e-f538-436e-aae8-dfb79ec747e8" /> ##### Validation focus <img width="1166" height="135" alt="image" src="https://github.com/user-attachments/assets/89abb73b-a624-406f-9736-3bf38bb8a923" /> ##### Addon lifecycle <img width="1166" height="591" alt="image" src="https://github.com/user-attachments/assets/14a95891-84d1-4073-a009-bc0eab94f114" /> ### Downstream repositories I walked the trigger map in `docs/agents/contributing.md` against the diff, file by file. This PR changes field descriptions, adds the `x-cozystack-no-enable-switch` schema keyword on three addon objects, and changes the console. No field is added, removed or renamed, and no default, version enum, `kind`, `plural`, `release.prefix`, output Secret or Service changes, so none of the terraform provider triggers fire. No package is added or removed, and nothing changes in `packages/core/platform/values.yaml`, the variants, `hack/` or the node prerequisites. cozyvalues-gen itself is unchanged, since the keyword goes through its generic `@x-*` passthrough. The kubernetes reference page on the website regenerates from `README.md` on a stable tag, which is automated rather than a follow-up. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note fix(dashboard): Ki-range sizes now render as Ki instead of raw bytes, the tenant picker is hidden on cluster-scoped admin pages, capacity drill-downs distinguish a permission error from a broken page, an immutable field whose parent object is absent is now applied, a blocked submit scrolls to the field that blocked it including fields inside maps and the source and dropdown widgets, and the cluster addons with no enable switch now say so instead of showing a toggle that never appears ``` |
||
|
Aleksei Sviridkin
|
1b0a5a2829 |
fix(velero): bump velero-plugin-for-aws to v1.14.4 so backups work on R2 (#4834)
## What this PR does Bumps the `velero-plugin-for-aws` init container in `packages/system/velero/values.yaml` from `v1.14.1` to `v1.14.4`, and updates the pin in `tests/velero_test.yaml`. `v1.14.1` sets `x-amz-tagging` on every `PutObject`, even when the BackupStorageLocation configures no tags, in which case the header is empty. Cloudflare R2 rejects that with `501 NotImplemented: Header 'x-amz-tagging' with value '' not implemented`. Velero then cannot upload backup metadata, so every Velero backup to an R2-backed location fails. That includes Cozystack's own `cozy-default` BackupStorageLocation when the platform backup bucket is on R2. Upstream fixed this in v1.14.3: velero-plugin-for-aws#309 (a backport of #299, "Only set PutObject Tagging when tags are configured"). `v1.14.4` is the current patch release of the 1.14 line. Its only change on top of v1.14.3 is CVE dependency bumps (#336). v1.14.3 itself also carries #310 (SSE-C presigned URLs), #313 (no amz-checksum encapsulation when `checksumAlgorithm=""`) and CVE/Go bumps. The plugin's compatibility table lists `v1.14.x` for Velero `v1.18.x`, which is what the chart ships (`velero:v1.18.1`), so this stays inside the supported pairing. Testing done: - `make test` in `packages/system/velero` (helm-unittest v1.1.2): 7 passed, with the existing init-container pin assertion moved to `v1.14.4`. - `helm template` renders `velero/velero-plugin-for-aws:v1.14.4` as `initContainers[0]` of the `velero` Deployment. - On a Cozystack v1.6.4 staging cluster with the backup bucket on Cloudflare R2: before the bump, Velero backups failed on the empty `x-amz-tagging` header. After pinning the same plugin image through a Package values override (`docker.io/velero/velero-plugin-for-aws:v1.14.4@sha256:c85a7fa803569e3128c33e4f5766f84ab156c8d171c9f1dd2715581d45ce98fa`), all of our volume backup and restore drills pass. That covers CSI snapshots with the Kopia data mover to R2, and incremental backups confirmed. Backwards compatibility: same plugin minor line and the same Velero version. The init container image changes, so the `velero` Deployment rolls once on upgrade. Users who never set `tagging` on a location now get no tagging header at all; users who do set it get the same header as before. The reference stays in the existing shape (tag only, no digest), like the current `v1.14.1` line. If you'd rather pin third-party init containers by digest, the v1.14.4 multi-arch index digest is `sha256:c85a7fa803569e3128c33e4f5766f84ab156c8d171c9f1dd2715581d45ce98fa`. ### Screenshots Not a UI change. ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: Trigger map walked against the diff: a third-party image tag in a system package values file and its test; no app schema, platform values, names or tooling. Fixes #4852 ### Release note ```release-note fix(velero): velero-plugin-for-aws is bumped from v1.14.1 to v1.14.4, which no longer sends an empty x-amz-tagging header, so Velero backups work against S3-compatible stores that reject it, such as Cloudflare R2. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Updates** * Updated the AWS backup plugin used by Velero to version 1.14.4. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
cd1345e661 |
fix(redis): re-send the Sentinel auth-pass when the operator resets a Sentinel (#4833)
Fixes #4851 ## What this PR does Adds a downstream patch to the redis-operator image (`packages/system/redis-operator/images/redis-operator/patches/unauthenticated-sentinel.diff`) so that a Sentinel which lost its `auth-pass` is repaired by the operator instead of being reset forever. ### The failure After a node power cycle on a Cozystack v1.6.4 cluster (3 nodes, Talos, HA Redis with `authEnabled: true`), the Sentinel pod on that node came back monitoring the correct master address, but with no `auth-pass`. The master answered it with `NOAUTH`, it reported the master as `s_down,disconnected`, and `SENTINEL CKQUORUM mymaster` on it returned `NOQUORUM 1 usable Sentinels`. The operator logged `mismatch number of sentinels in memory. resetting` on every resync and sent `SENTINEL RESET *`. That does not touch `auth-pass`, so the Sentinel never recovered on its own: the instance keeps running with two working Sentinels out of three until someone deletes that pod. One more failure then leaves Sentinel without a majority. The mechanism, which I reproduced locally with Redis 8.6.2 (script and output in #4851): 1. The pod restarts in place (same pod, same IP), so the `sentinel-config-copy` init container writes the operator's initial `sentinel.conf` again: `sentinel monitor mymaster 127.0.0.1 6379 2` and no `auth-pass`. 2. The other Sentinels still know that address and keep sending their hello messages to it directly. A failover has raised the config epoch, so the restarted Sentinel adopts the current master address from a peer (`+config-update-from sentinel ... +switch-master mymaster 127.0.0.1 ... <current master>`) before the operator looks at it. 3. `CheckAndHeal` then finds the right address in `CheckSentinelMonitor` and skips `NewSentinelMonitor`, the only call that sends `SENTINEL SET <master> auth-pass`. 4. `INFO sentinel` reports `status=sdown`, so `CheckSentinelNumberInMemory` fails and `RestoreSentinel` sends `SENTINEL RESET *`. The reset keeps the empty `auth-pass`, and the cycle repeats. The same code is on `main`: freshworks-oss v3.3.5 sets `auth-pass` only in `MonitorRedisWithPort`, and none of the three patches Cozystack carries touch this path. ### The change `RestoreSentinel` sends `SENTINEL SET <master> auth-pass <password>` right after `SENTINEL RESET *` when the RedisFailover has auth enabled. It uses the same password `NewSentinelMonitor` uses (`k8s.GetRedisPassword`), the same TLS config, and the same master name (`rf.MasterName()`, so `disableMyMaster` is respected). - It only runs on the unhealthy path. `RestoreSentinel` is called only when a Sentinel's view is already wrong: its sentinel or replica count does not match, or its status is not `ok`. A healthy Sentinel is never touched. - It does not disturb a working Sentinel. `SENTINEL SET auth-pass` drops the Sentinel's links to the monitored instances, but the `RESET` just before it has already done that. - Without auth, `GetRedisPassword` returns an empty string and nothing is sent, so the behaviour is exactly as before. - Bootstrap mode goes through the same function and gets the same password `NewSentinelMonitorWithPort` already sends there. Patch contents: a `SetSentinelAuthPass` method on `service/redis.Client`, its mockery-style mock, the two-step `RestoreSentinel`, and `TestRestoreSentinel` (5 cases: auth off, auth on, reset error, unreadable Secret, `SET` error). The file name sorts after `tls.diff` on purpose: the patch is written on top of it (same functions, new `tlsConfig` parameters), and the Dockerfile applies `patches/*.diff` in glob order. If you prefer numbered patch names, I can rename it. Like `tls.diff`, this belongs upstream too: the same fix is open as freshworks-oss/redis-operator#90. This carried patch can be dropped once a release containing it is vendored here. ### Why not a quorum-checking liveness or readiness probe The RedisFailover CRD does allow `spec.sentinel.customLivenessProbe` / `customReadinessProbe`, so a `SENTINEL CKQUORUM` probe could be set from the chart. I looked at that first and decided against it: - A liveness restart does not repair this. It restarts the container, not the pod. `sentinel.conf` lives on an `emptyDir` that survives a container restart, and only the init container rewrites it, on pod start. The restarted Sentinel reads the same file without `auth-pass` and fails again, so the probe would restart it in a loop. - `CKQUORUM` does not reliably detect it. In the local reproduction the broken Sentinel still answered `OK 3 usable Sentinels`, because its peers reach it directly. On the cluster it answered `NOQUORUM`. What does show the problem every time is `status=sdown` in `INFO sentinel`, which the operator already reads. - It hurts in real outages. With two of three nodes down, a quorum-based liveness probe would restart the last Sentinel, and a quorum-based readiness probe would empty the `rfs-` Service, at the moment clients most need it. The operator already detects this state and already runs a repair for it. The repair just did not include the password. ### Testing done - Applied the four patches to a fresh v3.3.5 tarball in Dockerfile order (`git apply patches/*.diff`). Then ran the Dockerfile's test step: `go test .` and `go vet -tags integration .` in every directory the patches touch, all 11 pass. Also ran `GOOS=linux GOARCH=amd64 go build ./cmd/redisoperator`. I could not run `make image` because Docker was not available on my machine. - `TestRestoreSentinel` fails on 3 of its 5 cases without the `heal.go` change and passes with it. The existing `operator/redisfailover/...` and `service/redis` tests pass unchanged. - End-to-end against real Sentinels (Redis 8.6.2, local): master + replica with `requirepass`, three Sentinels configured the way the operator configures them, a `SENTINEL FAILOVER`, then one Sentinel restarted on the same port with the operator's initial config. Result: that Sentinel switched to the new master from a peer's hello and sat in `status=sdown`, `flags s_down,master,disconnected`. `SENTINEL RESET *` alone left it in `sdown`. The patched `service/redis` client (`ResetSentinel` then `SetSentinelAuthPass`) brought it to `status=ok,...,slaves=1,sentinels=3`. - The mock was written in the format mockery v2.45.0 generates; v2.45.0 itself does not build with Go 1.26+ (`golang.org/x/tools` v0.17.0), so I could not regenerate it mechanically. Backwards compatibility: no API or chart change. The operator image has to be rebuilt to pick up the patch, like the existing patches (the image digest in `packages/system/redis-operator/values.yaml` is stamped by the build). Instances without auth are unaffected. ### Screenshots Not a UI change. ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: Trigger map walked against the diff: one new file under `packages/system/redis-operator/images/redis-operator/patches/`; no values, schema, CRD, name or tooling change. ### Release note ```release-note fix(redis): the redis-operator now re-sends the Redis password to a Sentinel it resets, so a Sentinel that restarted in place (for example after a node reboot) and lost its auth-pass recovers on the next check instead of staying down until its pod is deleted. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Sentinel recovery now restores the Redis authentication password after a successful reset when a password is configured. * Recovery stops if the reset fails and reports errors encountered while retrieving or applying the password. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
gireassen
|
525814d399 |
fix: typo in monitoring-agents values.yaml
Signed-off-by: gireassen <80508012+gireassen@users.noreply.github.com> |
||
|
Fedor Batonogov
|
68cd1028bd |
feat(kubernetes-nodes): let CDI trust a self-hosted Talos image factory
talos.imageFactoryURL is documented for self-hosted factories and mirrors in air-gapped, rate-limited or flaky-egress environments. Such an endpoint is normally served with a certificate from an internal CA, and CDI — which trusts only its system store — refuses the import with "x509: certificate signed by unknown authority". The DataVolume never completes, no worker joins, and the release sits in install until it times out. DataVolume.spec.source.http.certConfigMap exists for exactly this, but the chart rendered source.http.url alone and no value reached the field. Add an optional talos.imageFactoryCA taking the CA in PEM form. When set, the chart renders it into a ConfigMap in the release namespace — CDI requires certConfigMap to sit alongside the DataVolume — and references it from the worker DataVolume on the HTTP import path; a pool cloning a golden image via osImage.builtin builds no source.http and renders neither. When empty, nothing is rendered and the output is byte-for-byte what it was. CDI appends the bundle to the system pool rather than replacing it, so a release pulling from a publicly-trusted endpoint keeps verifying either way. The value is emitted verbatim into a ConfigMap readable by anything that can read the namespace, so the render fails closed on private key material and on anything that is not complete PEM certificate blocks. Those guards live in a new validate-only cozy-lib.tls.validateCACert helper that takes the caller's field name for its messages, and cozy-lib.tls.caCertSecret is refactored onto it, so the check exists in exactly one place. Assisted-by: LLM Signed-off-by: Fedor Batonogov <fedor@batonogov.ru> |
||
|
Yasar Rahman
|
8580a9d46d |
feat(redis): size the Sentinel pods separately from Redis
Every Sentinel pod gets the Redis pods' resources, so the three Sentinels of an instance reserve three times a Redis replica's memory while holding only their configuration and the failover state. On a t1.nano instance that is 3 x 128Mi while the VPA recommender's uncapped target for a Sentinel container is 16Mi, and the waste grows with every larger preset, because the dataset that drives the Redis sizing never reaches a Sentinel. sentinel.resources and sentinel.resourcesPreset follow the convention of the top-level pair, and sentinel.resourcesPreset falls back to resourcesPreset. Explicit Redis resources are not carried over once the sentinel block sets either key, since they were sized for the dataset. An empty sentinel.resources map counts as unset, as an empty top-level resources does. An empty sentinel block keeps today's sizing, so existing instances render unchanged and an upgrade does not roll their Sentinels. The Sentinel WorkloadMonitor reports the preset the Sentinels actually use. Signed-off-by: Yasar Rahman <yasar.rehman@gmail.com> Assisted-by: LLM |
||
|
Yasar Rahman
|
f6f879cf38 |
fix(postgres)!: refuse plaintext sessions on external instances
CloudNativePG offers TLS but its built-in last pg_hba rule, host all all all, also accepts plaintext, so a client outside the cluster that connects with sslmode=disable gets an unencrypted session. tls.enabled only decides whether the external hostname goes into the certificate and cannot prevent this. When external is true the chart now renders spec.postgresql.pg_hba with hostssl all all all scram-sha-256 followed by host all all all reject. CloudNativePG places user rules after its fixed rules and before its default rule, and the first match wins, so only TLS sessions are accepted. The pod network cannot be told apart from an external client, so in-cluster clients are held to the same rule; libpq's default sslmode=prefer already negotiates TLS. The new tri-state tls.required follows external when omitted. Setting it to false keeps accepting plaintext on an external instance and true requires TLS on an in-cluster one. The hostssl rule uses the same password method as CloudNativePG's own default rule (md5 before PostgreSQL 14, scram-sha-256 from 14), so existing md5 verifiers keep working on PostgreSQL 13. Rendering fails when postgresql.parameters.ssl is off while TLS is required, since hostssl would never match and every remote session would be refused. BREAKING CHANGE: external clients that connect without TLS are refused after the upgrade. Set tls.required to false to keep accepting them. Assisted-by: LLM Signed-off-by: Yasar Rahman <yasar.rehman@gmail.com> |
||
|
Aleksei Sviridkin
|
f4bde9e50d |
fix(backups): delete the original PVC of an in-place VM restore without keepOriginalPVC (#4672)
<!-- Thank you for making a contribution! Here are some tips for you:
- Use Conventional Commits for the PR title: `type(scope): description`
- Types: feat, fix, docs, style, refactor, perf, test, build, ci, chore
- Scopes are not an exhaustive list — pick the most specific scope for
the change and extend the list when a genuinely new area appears.
Examples:
- System components: dashboard, platform, operator, cilium, kube-ovn,
linstor, fluxcd, cluster-api
- Managed apps: postgres, mariadb, redis, kafka, clickhouse,
virtual-machine, kubernetes
- Development and maintenance: api, hack, tests, ci, docs, maintenance
- Breaking changes: append `!` after type/scope (`feat(api)!: ...`) or
add a `BREAKING CHANGE:` footer
- If it's a work in progress, consider creating this PR as a draft.
- Don't hesistate to ask for opinion and review in the community chats,
even if it's still a draft.
- Add the label `kind/backport` if it's a bugfix that needs to be
backported to a previous version.
-->
## What this PR does
An in-place VMInstance restore with `keepOriginalPVC: false` reports
`Succeeded` without restoring the disks, and leaves every disk it
touched unable to come back. `prepareForRestore` deletes each DataVolume
with Orphan propagation and leaves the PVC in place, on the assumption,
stated in the `deleteDataVolume` comment, that Velero overwrites it.
Velero does not overwrite a PVC. Its CSI restore action returns early
for a claim that already exists, so no DataDownload is ever created, and
with `existingResourcePolicy: update` the merge patch it attempts
instead is rejected because a bound claim's spec is immutable. All that
reaches the claim is the labels-only fallback patch, which also drops
the `cdi.kubevirt.io/allowClaimAdoption` annotation the resource
modifier added.
The claim left behind then blocks the disk for good. Orphan propagation
has removed its owner reference to the DataVolume, and it lacks the
`cdi.kubevirt.io/storage.populatedFor` annotation that
kubevirt-velero-plugin writes on the backed-up copy, so when the
HelmRelease resumes, the CDI webhook refuses the DataVolume it creates
with `Destination PVC <ns>/<name> already exists`, on every reconcile.
Deleting the disk through the API leaves the PVC behind, and a new disk
of the same name fails the same way.
Observed on a v1.6.3 cluster, for a VMInstance restore with
`keepOriginalPVC: false` whose disk was attached to the VM. The Velero
log for the restore, trimmed:
```text
level=info msg="Retrieved per-restore resource modifiers from configmap cozy-velero/restore-modifiers-..."
level=warning msg="PVC already exists and ExistingVolumeDataPolicy is not in-place restore. Skip restore this PVC." Action=PVCCSIRestoreItemAction PVC=tenant-datalab/vm-disk-e2edisk
level=info msg="Applying resource modifier patch on tenant-datalab/vm-disk-e2edisk"
level=warning msg="patch attempt failed for /v1, Kind=PersistentVolumeClaim tenant-datalab/vm-disk-e2edisk: PersistentVolumeClaim \"vm-disk-e2edisk\" is invalid: spec: Forbidden: spec is immutable after creation except resources.requests and volumeAttributesClassName for bound claims"
level=info msg="backup/restore labels successfully updated for PersistentVolumeClaim tenant-datalab/vm-disk-e2edisk"
```
`velero restore describe --details` lists the PVC as `(failed)` and the
Restore is `Completed` with two warnings. Afterwards the claim had its
original creation timestamp and UID, no owner reference, no
`allowClaimAdoption`, no `populatedFor`, and the disk's HelmRelease was
`Ready=False` with the webhook error above. That cluster runs a Velero
build from `main`, whose wording is quoted above; the released v1.17.1
and v1.18.3 return early at the same point with `PVC already exists.
Skip restore this PVC.` (`pkg/restore/actions/csi/pvc_action.go`).
The fix deletes the PVC when `keepOriginalPVC` is false, only once its
DataVolume is confirmed gone so that CDI cannot recreate it, and holds
the Velero Restore until the claim has actually disappeared. A claim
still mounted stays `Terminating` behind `kubernetes.io/pvc-protection`,
and creating the Restore then would hit the same existing-claim path.
Velero then creates the PVC from the backup, the data mover fills it,
and the recreated DataVolume adopts it through `populatedFor`. A failed
deletion now fails the RestoreJob instead of letting it report
`Succeeded` over the old data. Before
|
||
|
Aleksei Sviridkin
|
d28834231c |
fix(vm-disk)!: refuse a golden-image clone CDI would leave unbound
When CDI clones a golden image into a StorageClass other than the one the golden PVC lives in, its csi-clone path, and its snapshot path once it gets a VolumeSnapshotClass of the provisioner, check the two classes for a common driver, a matching volume mode and room to expand, and never compare the class names. A target class of the same provisioner therefore gets no host-assisted fallback and the clone is left to the CSI driver. LINSTOR creates that clone next to the source data, so on a target class that does not allow remote volume access from every node, such as a node-local one, the temporary clone PVC stays unbound with nothing surfaced to the user. Refuse such a disk at render time, mirroring the planner's inputs: the CDI override or the target StorageProfile's strategy, the snapshot class CDI would pick, the golden's driver as its PV records it, the target's provisioner, the volume modes and the target's expansion setting, and refuse only a LINSTOR target whose remote access policy, parsed the way linstor-csi parses it, is not plainly "from anywhere". A snapshot class both StorageProfiles name but that does not exist is refused as well, because CDI then fails to plan the clone instead of falling back. An empty storageClass is resolved the way CDI resolves it for a kubevirt DataVolume. A disk whose DataVolume or PVC already exists is exempt, since CDI can garbage-collect a completed DataVolume. Combinations that fall back to a host-assisted copy, targets reachable from any node, and anything else the lookups cannot find still render. This changes behaviour for a new disk in a LINSTOR class without remote access from every node, and for one whose StorageProfiles name a snapshot class that does not exist: both rendered before and are refused now. The way out is the golden image's class, or the copy clone strategy. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
ddd00f8639 |
feat(platform): pass multus resources from networking.multus.resources
The multus chart takes its resources from values, but the platform renders the cozystack.multus Package with stageCniPlugins alone, and an edit to that child Package is reverted by the platform reconcile. A running cluster therefore had no way to raise the multus limits. networking.multus.resources is passed to the Package only when set, so an unset key leaves the chart default in charge. A value that is not a map stops the render here; the multus chart keeps refusing a render without a memory limit or request. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
dca2e4ff0b |
fix(multus): drop the CPU limit and make resources configurable
kube-multus serves the CNI call for every pod sandbox on its node, and its 100m CPU limit was hardcoded in the patched upstream template. After a CNI outage a node had ~600 dead sandboxes and 220 pods waiting: multus was throttled in every CFS period, calls outlived kubelet's two-minute CRI deadline, each retry grew the queue, and the node never recovered. With the CPU limit lifted the 1Gi memory limit OOM-looped; 2 CPU and 4Gi cleared the backlog in about three minutes. Resources now come from values, defaulting to the same requests, no CPU limit and a 4Gi memory limit. The memory limit stays so the pod cgroup keeps memory.max and remains outside the Talos OOM handler's candidate set. Since an explicit null in a values override could drop either memory key, the render now fails without limits.memory or requests.memory. Without the request it defaults to the limit, and a node with less allocatable memory than that is left without multus. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
be2387323b |
feat(gateway)!: reserve a passthrough listener's name by the spec alone (#4638)
## What this PR does This keeps the TLS-passthrough services on port 443 of the tenant Gateway and makes the passthrough rules hold on Cilium 1.20.2. It is stacked on #3343 and has to land with it (stack #4717). On 1.20, upstream Cilium marks an HTTPS-terminate listener and a TLS-passthrough listener on one port `Conflicted` when their hostnames overlap, and drops both from Envoy. That took `*.<apex>` and the `api`, `vm-exportproxy` and `cdi-uploadproxy` passthrough listeners down together on every tenant Gateway in `dns01` and `existingSecret` mode (#3912). #3343 now ships a patched operator that conflicts the pair only when the hostnames are equal, so the layout stays as it is on main: one Gateway, one address, everything on 443. What remains is the equal-hostname case and the cleanup that 1.20 allows. Under `http01`, a name a passthrough listener answers is now reserved by the spec alone. Before, the controller dropped the terminate listener for such a name only once a TLSRoute was attached to the passthrough listener and its backend Service resolved, which copied how Cilium builds filter chains. Without a working TLSRoute, an HTTPRoute on `api.<apex>` kept its terminate listener next to `tls-api`, and on 1.20 that equal-hostname pair takes both listeners down. Now such an HTTPRoute gets no listener and no certificate, TLSRoute or not. If all its hostnames are reserved it reads `Accepted=False` with `NoMatchingListenerHostname`. If it also claims a free hostname it stays `Accepted` and is served there. The backend lookup, its Service and ReferenceGrant watches and their RBAC rules are gone. Other changes: - `tlsPassthroughListeners` is accepted under `dns01` and `existingSecret`. The old refusal relied on 1.19.5 serving all ports from one Envoy listener; 1.20 splits ports whose SNI overlaps. - A TenantGateway reads `Ready=False` with reason `GatewayClassUnsupported` when its GatewayClass lists features in `status.supportedFeatures` but not `TLSRoute`, while it renders passthrough listeners. A class that lists nothing is not judged. Cilium 1.20.2 lists `TLSRoute`. - Comments, the README and one error message no longer describe Cilium 1.19.5 as the shipped release. - The gateway chart writes `tlsPassthroughServices` on the publishing tenant only, behind the same `gateway.enabled` switch and `publishing.exposedServices` filter as the platform TLSRoutes. Before, every tenant Gateway got the three passthrough listeners with nothing routed to them, and the reservation above would have taken those names from a child tenant's own HTTPRoutes. The uniform `allowedRoutes.kinds` on port 443 from #3087 stays. The Cilium bug behind it is fixed since 1.19.6, but several tests pin it, so removing it is a separate cleanup. ### Upgrade notes Only the publishing tenant keeps the `api`, `vm-exportproxy` and `cdi-uploadproxy` passthrough listeners. That is `tenant-root` unless `publishing.ingressName` says otherwise, and only for names in `publishing.exposedServices` while `gateway.enabled` is on. Other tenants lose these listeners on upgrade. Nothing shipped was attached to them, so a child tenant's own HTTPRoute on `api.<child-apex>` keeps its listener and certificate. Two narrow cases do change. On the publishing tenant under `http01`, an HTTPRoute on an exposed passthrough name loses its listener and certificate when the platform TLSRoute for that name forwards nowhere (the owning package is not installed, or its backends do not resolve). A TLSRoute attached by hand to a child tenant's `tls-*` listener loses its parent. To keep that listener, merge-patch `tlsPassthroughServices` into the tenant's `TenantGateway` after the upgrade. From then on the chart does not render the key there, and later upgrades leave the patch alone. `dns01` and `existingSecret` do not change: the wildcard listener still covers such a name, and the passthrough listener answers it by its exact name. Tested locally: Go tests for the controller, `go vet`, helm-unittest for `extra/gateway` and `cozystack-controller`, `make generate` and `make manifests` with no diff. The gateway e2e scenario checks that a child tenant renders no passthrough listener. It then declares `tls-api` and a passthrough listener on a native port on that tenant, checks that the tenant stays Ready with no route behind either, and checks the reservation against `tls-api`. Unit tests catch a regression in either change. In e2e, dropping the reservation turns the gateway suite red, and dropping the chart scoping does not, because CI never sets `gateway.enabled` (#4846). The controller was not run on a live cluster; the operator patch it depends on was, see #3343. ### Downstream repositories - [ ] No downstream repository is affected by this change - [x] [cozystack/website](https://github.com/cozystack/website) - follow-up: https://github.com/cozystack/website/issues/725 - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note feat(gateway)!: the tenant Gateway renders the api, vm-exportproxy and cdi-uploadproxy passthrough listeners only on the publishing tenant, for the names publishing.exposedServices lists while gateway.enabled is on. Under certMode http01 a name a TLS-passthrough listener answers no longer gets an HTTPS listener on 443, with or without a TLSRoute behind it. On the publishing tenant, an HTTPRoute on such a name whose TLSRoute forwards nowhere loses its listener and certificate. A TLSRoute attached by hand to a tls-* listener of another tenant loses its parent. An HTTPRoute with some reserved and some free hostnames used to be rejected whole; it is now Accepted and its free hostnames get a listener and a certificate. tlsPassthroughListeners is accepted under dns01 and existingSecret. A TenantGateway whose GatewayClass does not list TLSRoute in its supported features reads Ready=False while it renders passthrough listeners. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * TLS passthrough listeners are supported with HTTP-01, DNS-01, and existing-secret certificate modes. Edge-terminated Gateways remain unsupported. * Declaring a passthrough hostname reserves it from HTTPS termination and certificate creation, even when no route is attached. * Passthrough listeners are rendered only for exposed services on the enabled publishing Gateway. * **Bug Fixes** * Gateways that declare passthrough listeners but explicitly lack TLSRoute support are now reported as not ready. * Routes targeting a hostname served by a passthrough listener on a different Gateway are correctly withdrawn. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
ad3f15d4f3 |
feat(gateway)!: reserve a passthrough listener's name by the spec alone
The TenantGateway controller withheld the HTTPS-terminate listener for a name a passthrough listener answers only once a TLSRoute was attached there and resolved a backend, mirroring how Cilium builds its filter chains. That kept a served endpoint up on Cilium 1.19.5, but it tied every route's status to one implementation's translator and needed Service and ReferenceGrant watches to land the deferred decision. The shipped operator accepts a wildcard terminate listener beside a narrower passthrough listener on 443 and keeps conflicting every other overlap. A terminate listener for the passthrough name itself is not narrower, so on 443 the rule now protects the dataplane outright; on a native port Gateway API would serve the pair, and the rule holds as a policy that keeps a platform name with its passthrough listener. Reading it off the spec makes the outcome the same on every implementation. Under http01 an HTTPRoute claiming such a name gets no listener and no certificate whether or not a TLSRoute is attached. A route whose every hostname is reserved reads Accepted=False with NoMatchingListenerHostname; one that also claims a free hostname stays Accepted and is served there, as Gateway API accepts a route whose hostnames intersect at least one listener. dns01 and existingSecret are unchanged: their wildcard listener still covers such a name, and the passthrough listener answers it by its exact server name. The chart writes the passthrough services on the publishing tenant alone, so the names reserved by default are the ones the platform publishes there through its own TLSRoutes. The shape an upgrade changes is an HTTPRoute on such a name whose platform TLSRoute forwards nowhere, because it never attached (the package owning the service is not installed) or because none of its backends resolve: that route kept a terminate listener and now gets none. The backend resolution, its watches and the RBAC rules that served them go away. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Yasar Rahman
|
83aaa65ed1 |
fix(velero): bump velero-plugin-for-aws to v1.14.4 so backups work on R2
velero-plugin-for-aws v1.14.1 sets x-amz-tagging on every PutObject,
empty when the BackupStorageLocation configures no tags. Cloudflare R2
answers that with 501 NotImplemented ("Header 'x-amz-tagging' with value
'' not implemented"), so Velero cannot write backup metadata and every
backup to an R2 location fails, the cozy-default location included when
the platform bucket is on R2.

The plugin sends the header only when tags are configured since v1.14.3
(velero-plugin-for-aws#309, a backport of #299). v1.14.4 is the current
patch release of the 1.14 line, which upstream lists as the one
compatible with Velero 1.18, and adds only CVE dependency bumps on top
of v1.14.3.

Signed-off-by: Yasar Rahman <yasar.rehman@gmail.com>
Assisted-by: LLM
|



