mirror of
https://github.com/cozystack/cozystack.git
synced 2026-11-22 04:33:36 +09:00
f83db514b0eb88cefc2923d17aad59daccb4e358
7777
Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 Aleksei Sviridkin |
a3caa62e47 |
test(backups): make the nats and kafka-metadata exec-error cases able to fail
Both cases passed the expected kubectl error to the stub through an environment variable named on the command that runs the helper. The unit runner traces that command, with the value expanded, into the very stderr the case then greps, so the case stayed green with the helper's stderr sent to /dev/null. The stub now prints the message itself and the variable is only a flag. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
ead7048b35 |
refactor(backups): define the walkthrough wait helpers once
Every backup walkthrough carried its own wait_for_field, and most their own wait_hr_ready and wait_deleted: twelve, eight and two copies, which had already drifted into five, three and two bodies. A fix made in one copy did not reach the others, and a diagnostics change carried by hand between two of them once went into the wrong function and was caught only by reading the diff. The helpers now live in examples/backups/_lib/wait-helpers.sh, sourced by each walkthrough's 00-helpers.sh. Where copies differed, the shared body keeps the diagnostics any of them had: wait_for_field leaves kubectl's stderr attached, and wait_hr_ready prints the conditions and history dump on Stalled or timeout. Call sites and budgets are unchanged. A new unit test fails when any walkthrough defines one of these helpers again, which replaces the byte-identity pin between copies. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
5318b5e507 |
fix(backups): exec into a CLI Pod in the kafka topic-data demo
kafka_run seeded and read topics through a throwaway `kubectl run -i` Pod per call. That Pod's stdout returns over an attach that carries only what the container writes after the attach registers, so a CLI that finishes first reads as an empty reply with exit 0 -- the empty-read defect already fixed in the redis, nats and kafka-metadata demos. The topic count, dump and replication-factor checks all read that reply. Run one long-lived CLI Pod, keeping the restricted security context, and exec into it. It carries its own name and owner label so it cannot collide with the kafka-metadata demo's Pod in a shared namespace, and cleanup.sh removes it by that label. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
735486fc36 |
fix(e2e): say when a post-install-prep wait attempt hit its bound
When the outer timeout cut a `kubectl wait` attempt, nothing was printed: `timeout` is silent and kubectl dies on the signal. The timeout line then read "last kubectl error: none", which says the client had nothing to report rather than that it was killed mid-request. The attempt's exit status now names that case. The errors the loop prints also carry the script's prefix. The first NotFound shows up on every green run, since the release appears about a minute in, and without the prefix it reads like a failure when the log is scanned after one. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
5b4380dd3b |
fix(e2e): delete the failed S3 preflight object through a live tunnel
The exit trap stopped the port-forward before running mc rm, so the delete went to a closed port and failed every time, leaving the object behind and printing a warning that said nothing about why. The delete now runs first and the warning carries mc's own error, or says the delete timed out when mc was killed before it could write one. A PUT that timed out is now also treated as uploaded: it can land and still outlive its time bound, and the trap never tried to remove such an object. A PUT the server refused is not, so the common case of access that never went live does not end in a delete doomed to the same refusal. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
b6cd6ab682 |
fix(e2e): print the port-forward log when the S3 preflight client fails
mc alias set reaches the endpoint through the port-forward, so a tunnel that came up and then broke is a likely cause of that failure, and its log is the only record of it. The readiness and retry-timeout exits already print it; this one threw it away. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
71a943277f |
build(make): keep running bats unit files after one fails
Each bats file is its own make target, so a plain `make bats-unit-tests` stopped scheduling files at the first red one and never ran the rest, while the output looked like a finished suite. CI passes -k and was not affected; a local run was. The target now runs the files in a --keep-going sub-make, which still exits non-zero when any file fails and shares the caller's job slots and output sync. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
f023e2fa38 |
test(build): count build-*.sh scripts as compiling in the cross-compile check
The compile pattern only matched a script named exactly *build.sh, so the multus-cni builder, which compiles through upstream ./hack/build-go.sh, was never classified as compiling and the check skipped the stage while appearing to cover it. Allow a suffix after "build" in the script name, but not a directory separator, so a path through a build/ directory is not mistaken for a build script. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
0592d0e324 |
chore(ci): add area/openbao to the label set and the scope mapping (#4182)
## What this PR does Every openbao PR lands on `area/uncategorized`. The labeler has no scope entry for it, and there would be no label to apply if it did, so both #4168 and #4177 are sitting on the fallback right now. `labels.yml` puts the bar for a new area at three open issues on the topic, and openbao is at three: #2787, #2483 and #2793. The shape follows what is already there for a single shipped component, next to `area/kamaji`, `area/keycloak` and `area/cilium`. The mapping takes the plain `openbao` scope and `openbao-central` alongside it, because the platform instance lives in its own package and carries its own scope. Checked that every `area/*` and `kind/*` the labeler references is declared in `labels.yml`: 27 referenced, none missing, before and after this change. zizmor and the pre-commit hooks pass, and the embedded script still parses under github-script semantics. ### Screenshots No UI change. ### Downstream repositories Walked the trigger map against the diff. Nothing matches: the change is two entries under `.github/`, and no trigger in the map is keyed on the label set or the labeler. No package added, renamed or removed, no platform component or variant, no `values.schema.json`, no `ApplicationDefinition`, no `hack/` layout change, no namespace rename. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note NONE ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit - **New Features** - Added an `area/openbao` label for tracking issues and pull requests related to OpenBAO. - Updated automatic pull request labeling to apply this label to changes scoped to OpenBAO and OpenBAO Central. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
c96dcaa11a |
fix(e2e): bound the lookup behind each kubectl wait in post-install-prep
`kubectl wait --timeout` looked like a bound on the wait loop's calls, but it covers only the watch. The command first resolves the object with a plain GET that has no deadline, since no --request-timeout is set, so an apiserver that accepts the connection and never answers holds the wait loop, the most frequently repeated call in the script, just like the calls that were unbounded outright. Each attempt now runs under an outer timeout set a little above the attempt's own --timeout, so the wait still owns its normal expiry. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
08011cef09 |
fix(ci): escalate an edit to the shared backup walkthrough helpers
examples/backups/<app>/ selects that app's suite, and a directory whose name is no suite selects nothing. A helpers directory shared by every walkthrough, examples/backups/_lib/, falls into the second case: an edit to it alone produces an empty selection, which both lanes read as "skip Chainsaw", so a change reaching every backup round-trip would run none. It now escalates to the full suite like hack/e2e-chainsaw/_lib/. The set of suites that run a walkthrough is spread across the suites' own scripts, and a derived subset that misses one would fail open. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
603ff2871e |
docs(hack): drop file and branch counts from the selector comments
The comments explaining the unit/e2e bats split quoted how many files each side held, and the escalation helper how many branches call it. Every figure had gone stale: nothing checks them, and they move each time a bats file or an escalation is added. The Makefile expression quoted beside the bats claim is what defines the set, so the explanation stands without the number. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
a6ec30d56f |
fix(ci): discover Chainsaw suites written as chainsaw-test.yml
Chainsaw loads chainsaw-test.yml when a directory has no chainsaw-test.yaml, but select-e2e and select-install enumerated the .yaml name only. A suite spelled that way ran whenever the whole directory was handed to chainsaw, yet no escalation listed it and no edit to it could select it, so it silently dropped out of every narrowed run. select-install also sent find's errors to /dev/null inside a pipeline that reported sort's status, so a failed listing validated no suite at all and passed. It is now captured and fails validation. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
d777f2a0b3 |
fix(ci): select the suites that use seaweedfs instead of all of them
cozystack.seaweedfs-application mapped to a seaweedfs suite that does not exist, so every seaweedfs change reached nothing runnable and paid for the whole Chainsaw run. The suites that can regress from it are bucket, the backup round-trips that write to the tenant-root instance through its in-cluster S3 endpoint, and harbor, whose registry storage is a BucketClaim served by the seaweedfs COSI driver with no graph edge between the two. bucket alone would miss the CA and service-name paths the round-trips depend on. The test derives the expected set from the suites' own yaml, so a new suite that names the endpoint or a BucketClaim there fails it until it is mapped. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
e070bc7d1d |
fix(ci): escalate a per-suite Chainsaw path that names no suite
A path under hack/e2e-chainsaw/<dir>/ put <dir> into the selection without checking that it is a suite, leaving the final intersection to drop it. Alone the path escalated through the empty-selection backstop, but beside any path that contributed a suite the escalation vanished and the run narrowed to that suite with nothing on stderr. Shared material next to _lib/ or a suite nested deeper than discovery looks then went untested in exactly the pull requests that also touch an app. The directory name is now membership-tested where the path is classified, as the hack/e2e-apps/ arm already does, so the decision is a property of the path and names it. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
7e0bd9c403 |
fix(e2e): stop post-install-prep on a failed or killed pool listing
The storage pool listing was piped straight into awk, so its exit status was lost: a listing that failed, or one killed by its time bound, read as "no pools exist yet". The script then sent a create for every node, and on the nodes whose pool did exist the create failed with a reason unrelated to the actual failure. The listing now runs on its own, so a failure stops the script before any pool is created. A bound that fires leaves no text of its own: `timeout` prints nothing and kubectl dies on the signal before it can. The bounded calls therefore go through a wrapper that names the call it killed, so the log does not end on the step's announcement line. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
ff2a677fc0 |
fix(e2e): say why the MetalLB CRD and CDI StorageProfile waits failed
Both waits ran as `timeout N sh -ec 'until kubectl get ...'` with the read's output discarded. On elapse `timeout` exits 124 and `set -e` ends the script, so the last line in the log is the one announcing the wait: CRDs that are late and an operator that never got far enough to install them read the same. A shared deadline loop now polls quietly and, on the way out, reads the objects once more with stderr kept, so the log names which object is missing. The MetalLB wait also lists the metallb HelmRelease, whose state separates those two cases. The loop runs on the script's own clock, which lets the unit suite drive it with the virtual one. The unit suite's runaway guard in the sleep stub now kills its caller as well, because a failing exit status does not stop a loop that runs where set -e is off, and a guard that cannot stop the loop turns a broken deadline into a hung test. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
b9a3fd0e8b |
fix(e2e): name the blocking release when post-install-prep times out
When the linstor HelmRelease never goes Ready, the script reported a timeout on linstor and dumped the cozy-linstor pods and events. In two failing install runs the linstor release only sat behind a dependency chain (kubeovn -> piraeus-operator-crds -> piraeus-operator -> linstor), so the evidence it printed described the wrong release and said nothing about the one that was stuck. The timeout now lists every HelmRelease first. Each Ready message names the dependency it waits on, so the post-install-prep log names the release at the head of the chain. Signed-off-by: Aleksei Sviridkin <f@lex.la> Assisted-by: LLM |
||
|
Aleksei Sviridkin
|
3378711fb9 |
fix(e2e): keep kubectl stderr in the post-install-prep wait loop
The loop discarded stderr to stay quiet while an object is not created yet, since `kubectl wait` exits non-zero at once on NotFound. An expired credential or an RBAC denial exits the same way, so the loop retried a client that could never succeed for the whole budget and then reported a timeout on the object, pointing at the cluster while the cause sat in the client. Each attempt's stderr is now kept and printed whenever it changes, and the timeout line repeats the last one. A NotFound repeated every poll still costs a single line. The text is printed rather than matched to fail fast: apiserver restarts during install produce the same connection and auth errors transiently, and a match list would turn a slow link into a false failure. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
d07099f13c |
fix(e2e): bound the calls that do work in post-install-prep
The install step blocks in `wait` on this script, so a kubectl call that never returns does not fail the step: it holds it open until the job's own ceiling cancels the run, which leaves different evidence behind than a failed test. Only the waits carried a budget. The execs that create storage pools, the applies, the CDI patch, and the reads inside the LINSTOR node loop did not, and the loop's deadline is checked between iterations, on the other side of a call that hangs. The reads that explain a node-loop timeout were unbounded too, on the one path that runs only when the cluster is already unhealthy. Each call now runs under an outer timeout, and plain requests carry a client timeout strictly inside it so kubectl names the reason before the kill lands. The helpers take the bound as a prefix that stays empty when unit tests source them, since `timeout` would bypass the kubectl function those tests substitute. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
9ac67d76a2 |
test(tests): preserve Bats failure reports during fixture cleanup (#3848)
## What this PR does Test-level `EXIT` cleanup overrides the Bats TAP handler, so a failed assertion can disappear from test results. This moves cleanup in eight unit files after their assertions. Failed tests keep scratch files for inspection. Prerequisite for [the Bats runner change](https://github.com/cozystack/cozystack/pull/3849). Existing subshell traps in the OpenAPI and CAPK tests remain supported. Closes #3623 ### Validation `make unit-tests test-controllers -j4 --output-sync=target` passed. The converted files passed under Bats 1.14.0 and `dash`. A deliberately failed assertion produces `not ok` after this change, and the trap audit rejects an added test-level handler. ### Downstream repositories Test cleanup and its documentation only. No downstream consumer changes. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note NONE ``` |
||
|
Aleksei Sviridkin
|
15f57be6f9 |
feat(controller): expose bucket class on BucketClaim Workloads (#3501)
## What this PR does `WorkloadMonitorReconciler.reconcileBucketClaimForMonitor` builds a `Workload` for each `BucketClaim` but never read `spec.bucketClassName`, so nothing on the resulting `Workload` told a consumer which bucket class was in use (e.g. an encrypted class vs. a plain one). This PR reads `BucketClaim.spec.bucketClassName` and sets it as a `workloads.cozystack.io/bucket-class` label on the `Workload`, following the same `workloads.cozystack.io/*` labeling convention already used for KubeVirt instance-type/profile metadata elsewhere in this controller. A regression test (`TestReconcileBucketClaim_BucketClassLabelPropagated`) asserts the label is present with the correct value. Closes #3419 ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: ### Release note ```release-note feat(controller): expose bucket class on BucketClaim Workloads via the workloads.cozystack.io/bucket-class label ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Workloads created from ready BucketClaims include the associated bucket class label when a valid value is specified. * **Bug Fixes** * Invalid or empty bucket class values are omitted from Workloads. * Stale bucket class labels are removed when the associated claim does not provide a valid value. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Myasnikov Daniil
|
3111fa7802 |
chore(ci): add area/openbao to the label set and the scope mapping
Every openbao PR lands on area/uncategorized, because the labeler has no scope entry for it and there would be no label to apply if it did. #4168 and #4177 are both sitting on the fallback right now. labels.yml sets the bar for a new area at three open issues on the topic, and openbao is at three: #2787, #2483 and #2793. It also follows the shape already used for a single shipped component, next to area/kamaji, area/keycloak and area/cilium. Maps the plain `openbao` scope and `openbao-central` alongside it, since the platform instance lives in its own package and gets its own scope. Assisted-By: LLM Signed-off-by: Myasnikov Daniil <myasnikovdaniil2001@gmail.com> |
||
|
Aleksei Sviridkin
|
9d3661416b |
ci: drop unused packages:write from the pull-request workflow (#3422)
## What this PR does The `build`, `build-talos` and `finalize` jobs in `pull-requests.yaml` each requested `packages: write`, but none of them touches GHCR: the workflow's `REGISTRY` is OCIR and they authenticate with `OCIR_USER` / `OCIR_TOKEN`. The only GHCR login in the file is in `verify-release-candidate`, which has `packages: read` and is not touched here. The scope was dead. It is worth removing rather than leaving alone. GHCR pushes elsewhere in CI authenticate with `GITHUB_TOKEN` plus `packages: write` rather than with a stored secret, so on those paths the scope *is* the whole credential, so granting it on the `pull_request` lane hands every same-repo PR run a token carrying GHCR write authority that lane has no use for. Whether a given package would actually honour that write depends on its Actions access setting, which lives outside this repo, so this is least-privilege hygiene rather than a fix for a demonstrated exploit. It also brings the three jobs in line with the `permissions: contents: read` default the workflow already sets at the top level. The e2e job keeps its `packages: read`; only the write scope is removed. Verified: `build`, `build-talos` and `finalize` log in to OCIR only (`docker/login-action` with `OCIR_USER` / `OCIR_TOKEN`), the sole `ghcr.io` login is in `verify-release-candidate` with `packages: read`, unchanged. The file still parses as YAML after the change. ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: Walked the trigger map in `contributing.md` against the diff. It removes three permission lines from one workflow and changes nothing any downstream repository restates. The nearest entry is the `ccp` one on release-prep behaviour, which is scoped to `tags.yaml` and untouched here. ### Release note ```release-note NONE ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Chores** * Updated the build, Talos build, and finalization workflows to request read-only repository access. * Removed package write permissions from these workflows. * Registry login and image publishing remain configured separately and are unchanged. No other workflow behavior or processing steps changed. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Alexey Artamonov
|
d5fc723208 |
feat(monitoring): bound every traces store by disk usage
The distributed tracing design requires each traces backend to be disk-bounded, not only age-bounded, so a full volume cannot block ingest. retentionDiskUsageBytes was optional, so a store without it filled its volume and stopped taking spans; with a shared-central store that stops ingest for every tenant at once. A store without a byte cap now drops its oldest day once its filesystem is 80% full. VictoriaTraces refuses to start with both limits set, so a byte cap, when given, replaces the percentage one. It always keeps the last two days, which the values text now says. Signed-off-by: Alexey Artamonov <aleksei.artamonov@aenix.io> |
||
|
Alexey Artamonov
|
2d10565873 |
feat(tenant): let a tenant opt into shared-central tracing
tracingCentral turns the shared-central topology on for a tenant with its own Monitoring: it publishes _namespace.tracingCentral for the tenant's monitoring charts and renders the only two cross-boundary paths that topology needs, the collector and Grafana each to the tenant-root vmauth. Both come from one condition, so a tenant never exports to the shared store without the path, or gets the path without opting in, and tenant-root, which hosts the store, gets neither. The flag is written only for tenants that opt in: every application in a tenant reads that Secret, and a new key for all of them would re-upgrade them all on the platform upgrade. Signed-off-by: Alexey Artamonov <aleksei.artamonov@aenix.io> |
||
|
Alexey Artamonov
|
27b7376bb9 |
feat(monitoring): add a shared-central tracing topology
A per-tenant traces backend costs every tenant its own VictoriaTraces stack. A tenant can now send new spans to one shared store in tenant-root instead, switched on by _namespace.tracingCentral, which the tenant chart publishes and the apps API does not let an application set. tenant-root decides whether it hosts that store, with tracingCentralHost next to a cluster-mode store named generic. VictoriaTraces takes the tenant account from request headers and does no authorization of its own, so other tenants reach the store only through a vmauth in tenant-root; tenant-root itself, with whoever it admits to its Grafana, stays inside the trust boundary. Each central tenant gets a VMUser that pins an account derived from its namespace name and UID for both writes and reads and caps its requests in flight, which the collector's two export senders stay under; its collector exports and its Grafana reads with credentials the chart generates and keeps, and vmauth overrides any account a client sends. The chart owns those credentials because the operator publishes a VMUser's own Secret only once a VMAuth selects it; the collector rolls when they change, since it reads them at start. The vmauth internal routes, whose /metrics names every tenant's user, are served on a port tenants cannot reach, and the vmauth is sized by a VPA, spread across nodes under a disruption budget, has a WorkloadMonitor like the other monitoring workloads, and may reach the apiserver, where its config-reloader reads its config Secret. Renders refuse the states in which spans would be dropped with every object Ready: a central tenant while tenant-root hosts nothing, tenant-root dropping the hosting while central tenants remain, and the host flag without a store to host. Each refusal reads the other side at render time, so a concurrent opt-in and stop-hosting can pass both; the values text names that race and its recovery. At run time tenant-root's release is not Ready while the vmauth has failed. Only the collector's export moves: local stores the tenant still lists keep rendering with their datasources, because the switch belongs to the parent tenant and the stores to this one, and the one-store limit of the collector holds in both modes, since turning central off makes it export locally again. tenant-root never counts as central. Signed-off-by: Alexey Artamonov <aleksei.artamonov@aenix.io> |
||
|
Aleksei Sviridkin
|
c983b5c404 |
fix(linstor): use severity warning instead of warn in piraeus-datastore alerts (#3799)
## What this PR does

Seven of the piraeus-datastore alert rules label themselves `severity:
warn`. Alerta, which the monitoring package ships as the alert sink,
validates that value and `warn` is not on its list. Every webhook
delivery for these alerts dies with a 500.

```
Severity (warn) is not one of security, critical, major, minor, warning,
indeterminate, informational, normal, ok, cleared, debug, trace, unknown
```

Alertmanager retries seven times and drops the notification, and the
alert never shows up anywhere. The affected rules are the LINSTOR/DRBD
ones, such as storage pool at capacity, lost quorum, unintentional
diskless and stuck resync. These are exactly the alerts you least want
silently dropped.

Found this on a v1.4.6 cluster where `linstorStoragePoolAtCapacity` was
genuinely firing. The cluster had 153 dropped notifications in 40
minutes and nothing in Alerta. Renaming the label to `warning`, which
the other three rules in the same file already use, stopped the failures
immediately and the alerts came through.

The same labels sit on `main` and in `v1.6.1`, so a backport to
`release-1.6` would be appreciated.

The test commit adds a bats guard so the next one gets caught in CI. It
walks every `PrometheusRule` and `VMRule` under `packages/` outside
vendored `charts/`, helm templates included, and fails on a severity
outside Alerta's default alarm model, which is exactly where `warn`,
`info`, `error` and `fatal` fall. Helm actions are stripped before the
file is read, so a rule behind a `{{- if }}` or an unquoted `{{
.Release.Namespace }}` is checked rather than skipped, and a file that
still does not parse fails the contract instead of thinning it out. On
the current tree that is 194 alerting rules in 41 scanned files.

The guard found one more on `main`. `DatabaseAutoscalerAtMax` in
`packages/system/keda/templates/alerts.yaml` carries `severity: info`,
which Alerta refuses the same way. It is renamed to `informational`, the
value the model has for that level and the one seven other rules in the
tree already use.

Moving that alert off `info` also stops `InfoInhibitor` in
`packages/system/monitoring-agents/alerts/general.rules.yaml` from
firing. That rule matches any `severity="info"` alert and carries
`severity: major`, so on `main` it usually reached Alerta whenever
`DatabaseAutoscalerAtMax` fired, even though the keda alert itself was
refused. After this change no rule carries `info`, so operators no
longer see that `InfoInhibitor` notification.

Fixes #2411.

### Screenshots

Not a UI change.

### Downstream repositories

Walked the trigger map against the diff. It touches severity labels
inside `packages/system/piraeus-operator/alerts/` and
`packages/system/keda/templates/`, plus a bats file under `hack/`. No
package is added or renamed, and there is no values schema, CRD, tooling
the satellites gate on or node contract change. Nothing downstream
restates these labels.

- [x] No downstream repository is affected by this change
- [ ] [cozystack/website](https://github.com/cozystack/website) -
follow-up:
- [ ]
[cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack)
- follow-up:
- [ ]
[cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack)
- follow-up:
- [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up:
- [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up:
- [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) -
follow-up:
- [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) -
follow-up:
- [ ]
[cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server)
- follow-up:
- [ ]
[cozystack/external-apps-example](https://github.com/cozystack/external-apps-example)
- follow-up:
- [ ] [cozystack/examples](https://github.com/cozystack/examples) -
follow-up:

### Release note

```release-note
fix(linstor): LINSTOR/DRBD alerts carried severity `warn`, which Alerta rejects, so they were never delivered. They now use the standard `warning` severity, and the keda at-max autoscaler alert moves from `info` to `informational` for the same reason.
```
|
||
|
harshitrwt
|
ffb6564f8b |
fix(controller): drop stale bucket-class label from BucketClaim labels before applying validated value
maps.Copy(workload.Labels, bc.Labels) can bring in a workloads.cozystack.io/bucket-class label directly set on the BucketClaim, which would survive unmodified when spec.bucketClassName is empty or invalid, leaving the Workload reporting a class that does not match the source BucketClaim. Signed-off-by: harshitrwt <harshit.rawat1804@gmail.com> |
||
|
Aleksei Sviridkin
|
2c2f2c194e |
fix(dashboard, foundationdb): show the connection ConfigMap to tenants (#4612)
## What this PR does Fixes #4611. Since #4148 a tenant may read the `<release>-config` ConfigMap that holds the FoundationDB cluster file, but the console has no view for ConfigMaps, so the connection string was still reachable only with kubectl. Chart: - `<release>-resourcemap` is rendered regardless of `monitoring.enabled`, because the console now reads it; - the tenant Role grants `get`, `list` and `watch` on `<release>-resourcemap` next to `<release>-config`, still by `resourceNames`, with no wider ConfigMap access. Console: - the application page gets a ConfigMaps tab when the application's resource map lists at least one ConfigMap in the same namespace; - each listed ConfigMap is read and watched with a `metadata.name` field selector, which RBAC checks against `resourceNames`, so a tenant never needs `list` on all ConfigMaps; - values are shown as plain text with a copy button, the cluster file needs no decoding; - a resource map that is missing or forbidden hides the tab, a listed ConfigMap that cannot be read shows the API error instead of looking empty, and a malformed map or an invalid name is reported. The tab is generic, but today only FoundationDB ships a resource map, so it is the only application that gets it. #3490 keeps `monitoring.enabled` as the switch for the resource map and asks whether the map should render unconditionally. This PR answers that for FoundationDB by rendering it always, so the wording in #3490 would need to follow if both land. Tests: `helm unittest` for the chart (6 tests), `tsc --noEmit`, `vitest run` (438 tests in 60 files) and `eslint` on the changed files pass. The new tests cover reading only the listed names in the active namespace, the watch, copying, a clipboard failure, a read denial, and malformed maps. The chart renders with `monitoring.enabled` true and false. ### Screenshots The ConfigMaps tab of a FoundationDB application, rendered by the console from this branch against a local stub API with synthetic data: 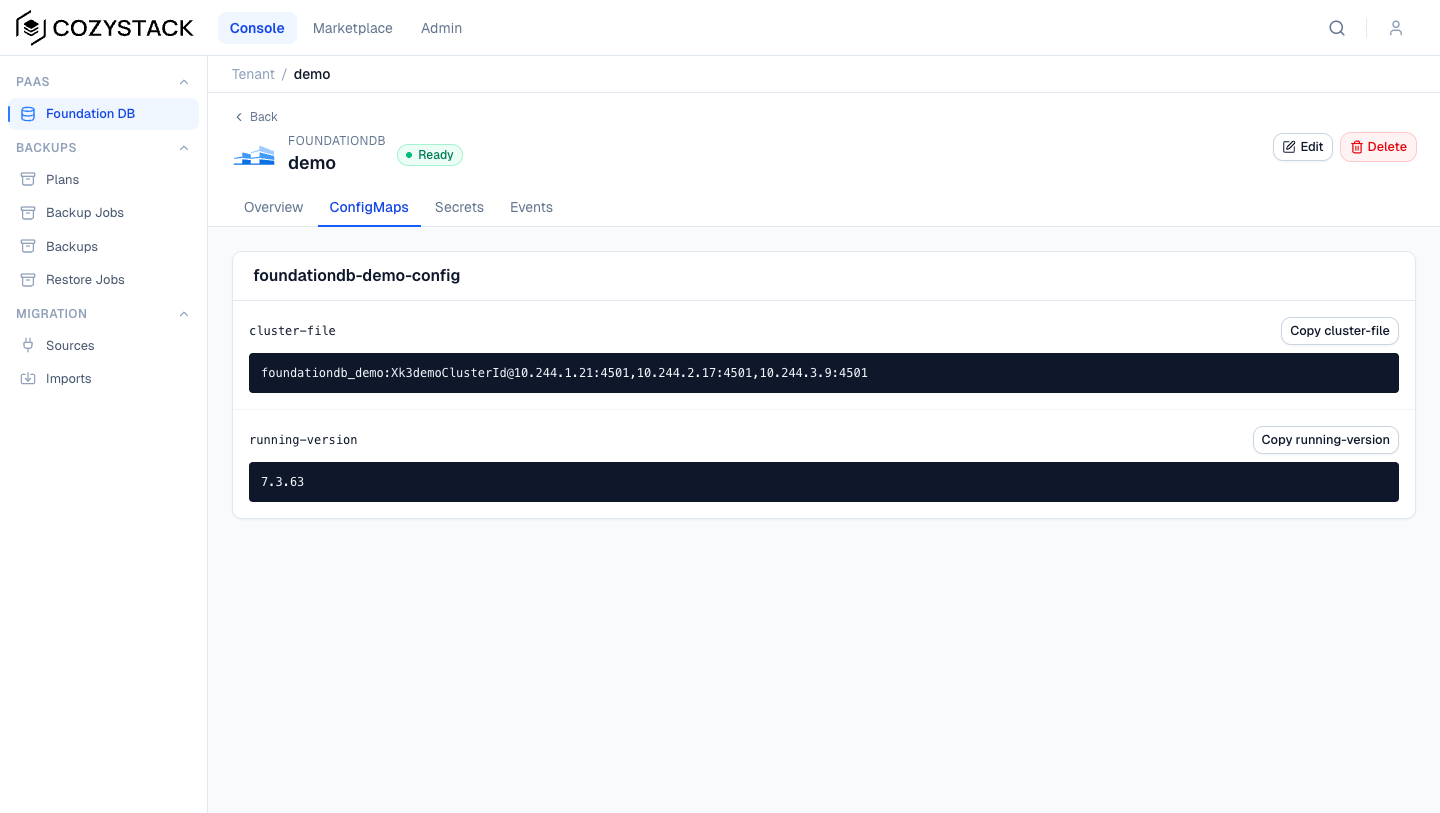 ### Downstream repositories Walked the trigger map against the diff: it changes a FoundationDB chart template and its test, and the console. No `values.yaml`, `values.schema.json`, README, CRD or `hack/` file is touched. The website FoundationDB page is generated from the chart README and says nothing about connecting, and the Terraform provider does not read these ConfigMaps. The console is vendored in this repository. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note fix(dashboard, foundationdb): the application page shows the FoundationDB connection ConfigMap with the cluster file to tenants who may read it ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Application details now include a ConfigMaps tab when configuration maps are available. View their values and copy them to the clipboard. * The tab displays loading, empty, unavailable, and error states. * **Bug Fixes** * The resource map remains available when monitoring is disabled, and its access permissions are included. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
scooby87
|
51155f1003 |
feat(postgres-operator): alert when the WAL archive backlog does not drain (#4572)
## What this PR does `LastFailedArchiveTime` compares a cluster's last failed WAL archival with its last successful one, so it resolves as soon as any segment gets through. Archiving that fails intermittently, or runs slower than the cluster writes WAL, keeps clearing that alert while the queue of segments waiting on the Postgres volume grows, until the volume is full and the database stops. The alert is also only a warning. This PR adds `CNPGWALArchiveBacklog`, a critical alert that fires when a primary's `archive_status` queue has not been empty once in 30 minutes. A healthy archiver empties the queue within seconds of each WAL switch, so a queue that never drains means point-in-time recovery is falling behind, whatever the archiver reports. Idle clusters and replicas have an empty queue and stay quiet. Validated live, since the repository has no rule-evaluation tooling: on a test cluster, two CNPG clusters archived into an object store that refused connections and into one that accepted them and never answered, while writing WAL continuously. The rule, evaluated by the root vmalert, fired for both. Over the previous seven days of the same cluster's metrics, none of its healthy clusters would have matched; those clusters carry light load, so a cluster whose archiver runs near its limit all the time has not been observed and would page, which is the intended reading of a queue that never drains. The unit test pins only that the rule ships in the rendered PrometheusRule as critical, since the rules reach the cluster through a file glob that drops a moved file silently. ### Screenshots Not a UI change. ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: The diff touches an operator chart's alert rules and its test; no path from the trigger map. ### Release note ```release-note feat(postgres-operator): page when a Postgres cluster's WAL archive queue has not drained for 30 minutes, which the existing archiving alert misses while some archives still succeed. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit - **New Features** - Added a critical alert for sustained PostgreSQL WAL archive backlogs. It triggers when the minimum observed ready archive status remains above zero over a 30-minute window, then stays pending for 10 minutes before firing. The alert describes potential impacts on point-in-time recovery and storage usage. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
c5865061a3 |
feat(dashboard): show a connection hostname for LoadBalancer services (#4035)
## What this PR does The Services tab on the application page shows a connection hostname under the External IP of every LoadBalancer Service, as `<service-name>.<suffix>`, also while the IP is still Pending. ClusterIP Services get nothing. The suffix is a new platform value, `publishing.serviceDomain`. It travels the same path as `cluster-domain` and `branding`: `_cluster.service-domain` in the cozystack-values Secret (leading and trailing dots stripped there), then `serviceDomain` in the dashboard's `config.json`, written only when non-empty. Empty by default, and with it empty the tab shows no hostname. There is deliberately no fallback to a tenant-derived name: the app charts certify `<release>.<tenant host>` while the LoadBalancer Services are named `<release>-external-write` and similar, so a name built from the tenant apex would match neither DNS nor the certificate. Showing nothing beats showing a name nobody publishes. The value is display-only. Nothing in the platform creates DNS records for it. Set it when your DNS already resolves `<service-name>.<serviceDomain>` to that Service's LoadBalancer IP, external-dns with a matching fqdn template for example. A CoreDNS `k8s_external` zone does not fit, it answers `<service>.<namespace>.<zone>`. The shown name is not the one in the app certificates, so a TLS client may see a SAN mismatch unless DNS and certificates are aligned by the operator, and two tenants with a release of the same name get the same hostname. The values comment says all of this. Left for follow-ups: reading `external-dns.alpha.kubernetes.io/hostname` from the Service as the first source (only the opensearch chart stamps it today), and a per-Service override annotation. Parked from review, not blocking: the Admin External IPs page does not show the hostname yet, the column header still says "External IP", and surrounding whitespace in the value is not trimmed. Closes #3112 ### Screenshots <img width="1200" height="360" alt="services-tab" src="https://github.com/user-attachments/assets/01e1f3e0-836e-41cc-b916-f675b62580cd" /> ### Downstream repositories `packages/core/platform/values.yaml` gains a key, so the hand-written table in `content/en/docs/next/operations/configuration/platform-package.md` on cozystack/website needs a row for `publishing.serviceDomain`. I will open that website PR once this one merges. No other repository restates this key: ansible-cozystack passes a fixed list of `publishing.*` keys that does not include it, and the terraform provider models app schemas, not platform values. - [ ] No downstream repository is affected by this change - [x] [cozystack/website](https://github.com/cozystack/website) - follow-up: a `publishing.serviceDomain` row in the platform-package table, opened after this PR merges - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: ### Release note ```release-note feat(dashboard): the application Services tab shows `<service>.<suffix>` under the external IP of LoadBalancer services when the new platform value `publishing.serviceDomain` is set ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit - **New Features** - Added an optional service domain setting for displaying LoadBalancer service hostnames in the dashboard. - When configured, services display hostnames in the format `<service-name>.<service-domain>` alongside external IP information. - Hostnames are shown only for LoadBalancer services and remain hidden when no service domain is configured. - Dashboard configuration now receives the service domain setting automatically, including support for custom domain formatting. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
harshitrwt
|
f41a500b07 |
test(controller): cover invalid bucket class label in reconcileBucketClaimForMonitor
A BucketClassName longer than 63 chars (valid as a Kubernetes object name, up to 253 chars) is not a valid label value, so the bucket-class label is skipped with an Info log rather than failing the Workload write. This can happen with SeaweedFS pool class names (<namespace>-<pool>-lock) when the tenant and pool names are both long -- a missing label in that case does not mean no class was set. Signed-off-by: harshitrwt <harshit.rawat1804@gmail.com> |
||
|
Aleksei Sviridkin
|
52c74beedd |
fix(api): let the garbage collector finalize Applications (#4610)
## What this PR does An application deleted with foreground or orphan propagation (`kubectl delete --cascade=foreground`, or any client that sends that `propagationPolicy`) could stay in deletion forever. Helm uninstalled the release and helm-controller removed `finalizers.fluxcd.io`, but the HelmRelease kept `foregroundDeletion` in `metadata.finalizers`, so the HelmRelease and its Application stayed terminating. We hit this on v1.6.4 with a Bucket and an OpenBAO application. An Application and its HelmRelease share one UID, so the garbage collector keeps a single graph node for both and may finalize it through the Application endpoint. The API never returned finalizers on an Application, and every update restored the HelmRelease finalizers from the live object. [`removeFinalizer`](https://github.com/kubernetes/kubernetes/blob/v1.33.1/pkg/controller/garbagecollector/operations.go#L85-L123) reads the owner, does not find the finalizer there and returns as if it had already been removed, so nothing ever took it off the HelmRelease. This PR: - returns `foregroundDeletion` and `orphan` in `metadata.finalizers` of an Application, and only those two; - carries an add or a remove of either of them from an Application update to the HelmRelease, as a change against the finalizers the update started from, so the result is the same when helm-controller or the garbage collector changes the list during the conflict retry; - keeps controller finalizers such as `finalizers.fluxcd.io` owned by the live object, so `helm uninstall` still runs before the release goes away; - copies the deletion timestamp and grace period from the live object into the rebuilt HelmRelease, so an update of a terminating release stays valid. `rest_garbage_collection_test.go` covers both finalizers with Helm finishing first and with the garbage collector finishing first, concurrent finalizer changes during the conflict retry, controller finalizers surviving an update, the cached HelmRelease not being mutated by the conversion, and an `UpdatedObject` that edits the object in place. All five tests fail on the current `main` without this change. `go test -race ./pkg/registry/...` passes. The tests use the controller-runtime fake client, so this has not been run against a live garbage collector with a patched cozystack-api yet. The same bug is in release-1.6. There the Update path has no finalizer carry-over at all, because #2914 is not backported yet, and its automatic backport #4577 currently carries conflict markers. A 1.6 backport of this fix should go on top of a working backport of #2914. ### Screenshots Not a UI change. ### Downstream repositories Walked the trigger map against the diff: it only changes how cozystack-api handles `metadata.finalizers` of Applications in `pkg/registry/apps/application`. No package, values, schema, CRD, `hack/` file or convention is touched. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note fix(api): an application deleted with foreground or orphan propagation no longer leaves its HelmRelease stuck with the foregroundDeletion or orphan finalizer ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Application updates now preserve Kubernetes deletion behavior, including foreground deletion and orphaning, even when concurrent changes occur. * Helm-managed protection metadata is retained during updates, and deletion timing details remain intact. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Myasnikov Daniil
|
57bf10acae |
test(e2e): stop bringing up the monitoring instance nothing looks at
The install turned monitoring on in the root Tenant and then waited up to 15m each on vmalert and vmalertmanager, vlclusters/generic, the shortterm and longterm vmclusters, the grafana-db CNPG cluster and the Grafana Deployment. No suite inspects any of it. The one Chainsaw suite that mentions monitoring, foundationdb, asserts a WorkloadMonitor, whose CRD ships with cozystack-controller and exists without the monitoring stack. The OIDC wiring of the monitoring chart is covered by its helm-unittest suite rather than by the e2e run. Those waits were not idle. The stack competes with the rest of the install for node capacity, and their own comment recorded that a slow VictoriaLogs start could fail the install on a pull request that never touched monitoring. The run was paying bring-up time and flake risk for a component it never looked at. The monitoring package stays installed: tenant-application declares dependsOn cozystack.monitoring-application, so dropping the package would leave the platform release unresolved. Only the tenant-root instance is turned off. The container lane's VictoriaLogs storage override stays. It does nothing while monitoring is off, and it keeps a run that turns monitoring back on from creating a replicated PVC on a lane that only has local storage. One check goes with the Grafana waits: the curl through root-ingress-controller at grafana.example.org, the only assertion that the root ingress routes to a backend. Grafana was its target because it happened to be installed, and pointing it at a seaweedfs host needs the expected response checked on a live stand first. Assisted-by: LLM Signed-off-by: Myasnikov Daniil <myasnikovdaniil2001@gmail.com> |
||
|
harshitrwt
|
882929ff86 |
fix(controller): skip bucket-class label when BucketClassName is not a valid label value
Signed-off-by: harshitrwt <harshit.rawat1804@gmail.com> |
||
|
harshitrwt
|
0c37fff5f4 |
feat(controller): expose bucket class on BucketClaim Workloads
Signed-off-by: harshitrwt <harshit.rawat1804@gmail.com> |
||
|
Aleksei Sviridkin
|
97fa2a619f |
feat(dashboard): show a connection hostname for LoadBalancer services
Users who provision a service through the dashboard had no hostname to connect to: the Services tab showed only the raw LoadBalancer IP, while the pre-1.4.0 UI composed <service>.<root host> for every Service. Render <service>.<suffix> under the External IP of every LoadBalancer Service (also while the IP is still Pending), and nothing for ClusterIP Services. The suffix is config.json serviceDomain, set by the platform value publishing.serviceDomain. There is deliberately no fallback: the app charts fix their external name as <release>.<tenant host> while the LoadBalancer Services are named <release>-external-write and similar, so a name derived from the tenant apex would match neither the DNS nor the certificate. Without a configured suffix nothing is rendered. Runtime config previously reached only the Shell as a prop; it is now published through AppConfigContext and read from there by the Shell and the Services tab alike, so a single test on the rendered version pins the wiring. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
67adfbce3c |
feat(dashboard): surface service-domain in the console config.json
The console loads config.json once at startup and treats a missing serviceDomain key as "show no hostname", so the chart copies _cluster.service-domain into config.json only when it is non-empty rather than shipping an empty string the SPA would have to special-case. The helm-unittest suite pins the unset, empty and set cases. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
d463e00da1 |
feat(platform): add publishing.serviceDomain for the dashboard Services tab
The dashboard has no way to show a connection hostname for a LoadBalancer Service: before 1.4.0 the old UI composed one from the Service name and the cluster's root host, and operators whose DNS publishes LoadBalancer IPs under a dedicated zone still need that. Add the suffix as a platform value and propagate it into the cozystack-values map as service-domain, next to cluster-domain and branding, so the dashboard chart can read it. The value is display-only and opt-in: empty (the default) means the console shows no hostname, because nothing in the platform publishes DNS for a guessed name. Leading and trailing dots are stripped here, the one place every consumer reads from, so an operator's ".svc.example.org." cannot render as "demo..svc.example.org."; the value is coerced to a string first because an unquoted numeric scalar would otherwise abort the whole platform render. The helm-unittest suite pins the empty default, a configured value landing in the Secret, the dot trimming and the numeric case. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
0bc3f9f25c |
fix(kubernetes): name TalosConfigTemplate by content hash (#3523)
## What this PR does Fixes #3515. `TalosConfigTemplate.spec` is immutable — the `vtalosconfigtemplate.cluster.x-k8s.io` webhook denies any mutation with `TalosConfigTemplate.Spec is immutable` — but the `talos-reconcile` Job applied it under a fixed `<release>-<group>` name on every reconcile. Once the template existed, **no change to the rendered worker machine config could ever reach the cluster**: the apply was rejected server-side while the HelmRelease stayed `Ready`. Reported with `machine.network.searchDomains` after a `clusterDomain` correction; the same held for `certSANs`, `machine.registries` and nameservers. - Name the `TalosConfigTemplate` `<release>-<group>-<6-char hash of its spec>`, mirroring the `KubevirtMachineTemplate` content-hash idiom the chart already uses, and point `MachineDeployment.spec.template.spec.bootstrap.configRef` at that name. A content change now creates a **new** template instead of attempting a rejected mutation, and CAPI rolls the workers onto it. - Extract the machine config into a single named template (`_talosconfigtemplate.tpl`) shared by the two consumers that have to agree on the name byte-for-byte: the Job, which embeds it in the heredoc it `kubectl apply`s, and the `MachineDeployment`, which hashes it into `configRef`. - Assemble the node group once, in `kubernetes-nodes.group`, and read it back at both call sites. Sharing the rendering was not enough: each file also built its own `$group` dict, so the two names agreed only by coincidence of the keys the spec helper happens to read. - The runtime values the Job substitutes (`${TALOS_CA_B64}`, `${SVC_IP}`, `${COREDNS_IP}`, tokens) stay shell placeholders and are deliberately **not** part of the hash: they are facts of an already-provisioned cluster, not chart inputs, so a certificate rotation or a Service re-address does not roll workers. ### What the shared spec carries Worker node pools live in the `kubernetes-nodes` chart, which owns `_talosconfigtemplate.tpl` outright: `make update` copies nothing from the parent chart. The helper renders everything `main` puts into the worker machine config, so the hashed spec is the one the cluster gets: - The heredoc escaping from #3513: backslash, dollar and backtick escaping on `talosVersion`, `installerRepository` and `schematicID`, the escaped `machine.registries.mirrors` block, and the `INVARIANT` comment above `data:`, which belongs in that file since it is where the next field will be added. The spec is still emitted from an unquoted heredoc in a host-cluster Pod, so an unescaped copy would be command injection. - The per-pool install image. `_talosconfigtemplate.tpl` calls `kubernetes-nodes.resolveOsImage` itself instead of reading `talos.schematicID` and `talos.version`, so a pool on `osImage.builtin` or `osImage.factory` reinstalls the schematic and version it actually booted. The install image is part of the hashed spec, so the hash has to be taken over the resolved image, or an `osImage` change would render a different config under an unchanged name. - The Proxmox branches: `nameservers` from `proxmox.dnsServers` where a KubeVirt pool points at the cluster's CoreDNS, and the kubelet's `cloud-provider: external`, without which the Proxmox cloud-controller-manager never initialises the Node. - `machine.kernel.modules`, emitted only when the pool resolves to a non-empty list. `kubernetes-nodes.group` carries every key those read, `podCpuLimit`, `podCpuRequest`, `osImage`, `proxmox` and `kernelModules` included. A key missing there is the failure this PR exists to prevent: with `kernelModules` read at one call site only, an explicit module list hashes to two different names and the `MachineDeployment` points at a template nothing creates. The `kubectl apply` stays `--server-side --force-conflicts` (#4163), so the Job is not OOMKilled on the merge path; with a content-hash name the apply is normally a create or a no-op, and server-side apply keeps the no-op cheap too. ### The replace-on-immutable path and the Role The runtime values stay outside the hash, so one failure is left that the hash cannot absorb: a new apiserver address renders a different spec under an unchanged name, and the webhook rejects it. The replace path from #4089 handles exactly that case and is kept, with its `kubectl delete` pointed at `${TCT_NAME}`. The talos-reconcile Role pins its TalosConfigTemplate `get`, `patch`, `update` and `delete` rights to the pool's own template, so it names the hashed template too. A server-side apply of a template that does not exist yet is still a PATCH on its name: a rule left on `<release>-<group>` would leave the Job Forbidden and the pool with no template to scale onto, with nothing turning red. The name-agreement guard below therefore covers the Role as well. ## Upgrade impact — please read **Existing clusters roll their Talos workers once.** The `configRef` moves from `<release>-<group>` to the hashed name; CAPI creates a new `MachineSet` for it and rolls machines onto it under the existing `RollingUpdate` strategy (`maxSurge: maxReplicas`, `maxUnavailable: 1`) plus the group's `MachineHealthCheck`. The rendered machine config itself is byte-identical to `main` for the same values, so this particular roll delivers no config change — it is the one-time cost of adopting the content-hash name, the same cost `KubevirtMachineTemplate` already paid. Proxmox pools roll the same way: the `ProxmoxMachineTemplate` name does not move, but the `configRef` does. **Until the new template exists, the pool cannot scale.** The Helm upgrade points the `MachineDeployment`'s `configRef` at the hashed name before the `talos-reconcile` Job has created that template, and there is no render-time ordering fix, since the template needs values Helm does not have. Existing workers are untouched in that window, but the pool is frozen: in CAPI v1.10.1, which this repository ships, `getTemplatesAndSetOwner` records the missing bootstrap template, and `rolloutRolling` then fails in `getAllMachineSetsAndSyncRevision` with `cannot create a new MachineSet when templates do not exist` and returns before it scales either the new or the old `MachineSet`. A replica change from the cluster-autoscaler therefore reaches no `MachineSet`: scale-up and scale-down both wait. On an upgraded cluster the Job's inputs already exist, so the window is normally a few seconds. **A failed `talos-reconcile` Job now blocks autoscaling, and nothing turns red.** After `backoffLimit: 30` the Job is not retried until the next Helm upgrade of the pool release, and the HelmRelease stays `Ready` meanwhile, as it did in #3515. Before this PR the same failure left the pool on its old template and still scaling; with it, the pool cannot scale at all until the template exists. Where to look: - the `MachineDeployment` `kubernetes-<cluster>-<group>`: its `ScalingUp` condition under `status.v1beta2.conditions` reads `Scaling up from N to M replicas is blocked because TalosConfigTemplate does not exist` (or `Scaling up would be blocked because …` while no scale-up is pending), and the capi-controller-manager logs carry `cannot create a new MachineSet when templates do not exist` for it; - whether a `TalosConfigTemplate` named after its `spec.template.spec.bootstrap.configRef.name` exists in the tenant namespace; - the `talos-reconcile` Job's status and Pod logs — but the Job has `ttlSecondsAfterFinished: 600`, so a failed Job and its logs are deleted ten minutes after it gives up. Past that, the `MachineDeployment` condition and the missing template are the only evidence left. The pre-existing fixed-name template is **not** deleted — the outgoing `MachineSet` still references it — and is garbage-collected with the `KamajiControlPlane` when the cluster is deleted. Hashed templates therefore accumulate, one per distinct machine config. Pruning them safely is filed as #4355 rather than widened into this PR. **The one roll is not the only one.** Hashing the whole rendered spec makes anything inside it a roll trigger, including two things that are not edits to this cluster's resource. For a pool sized by `instanceType`, the kubelet reservations come from a live `lookup` of the `VirtualMachineClusterInstancetype`, so a later platform-side edit to that instancetype rotates the name and rolls the pool again — and the `KubevirtMachineTemplate` hash this mirrors does not have that property, since it embeds the instancetype by name and never its resolved size. And `talos.registryMirrors` is inside the hashed spec, so setting or changing a mirror now rolls the pool rather than applying only to nodes created later; the field's documentation said nothing about this and now says it. The same holds on Proxmox for `proxmox.dnsServers`, and on every substrate for `kernelModules`: both are inside the hashed spec, so changing either rolls the pool, and the `kernelModules` documentation now says so instead of describing the fixed name as the current state. **The roll is not free on a node group holding a scarce resource.** From exercising this same rollout path on a production fleet of 13 tenant clusters, by rotating the `KubevirtMachineTemplate` hash on a GPU node group. `maxSurge: maxReplicas` is dangerous when the resource is constrained: with 6 GPUs and 1 free, CAPI created all 5 new machines at once and 3 sat `Pending` on `Insufficient nvidia.com/...`, each having already imported a 200 GiB disk. It converges, but it wastes a lot of import. The natural reflex, `maxSurge: 0` with `maxUnavailable: 1`, deadlocks instead: CAPI computes `maxScaledDown = available - (desired - maxUnavailable)`, which was `4 - 4 = 0`, so it removed no old machine while the new ones waited for exactly those machines to release their GPUs; nothing moved until `maxUnavailable` was loosened to 2. And the `MachineHealthCheck` amplifies both — at `maxUnhealthy: 100%` and `nodeStartupTimeout: 10m`, machines queuing for a GPU were declared unhealthy and remediated in a loop, three deleted and recreated while perfectly healthy, each iteration re-importing the disk. The per-node-group `nodeStartupTimeout` override fixes that, but the default is shorter than a plausible queue wait. Anyone upgrading a fleet with a GPU pool hits all three, and this PR is what starts the roll. ## Validation - `helm unittest packages/apps/kubernetes-nodes` passes, snapshots included. Pointing `configRef` back at the fixed name fails `nodegroup_test.yaml`, the snapshot and the name-agreement bats; dropping `osImage` from `kubernetes-nodes.group` fails the `worker_image_*` suites; removing the Proxmox nameserver branch fails `substrate_branches_test.yaml` and the Proxmox heredoc case. - `hack/check-talosconfigtemplate-name-agreement.bats` is new. The unittest suites pin each name against its own literal in its own file, so a divergence shows up as one literal having moved, which reads as a stale fixture and invites re-pasting the value. The guard renders the chart once and compares the Job's `TCT_NAME`, the Role's TalosConfigTemplate `resourceNames` and the `MachineDeployment`'s `configRef.name` against each other, so the failure states the invariant rather than a number. Asserted on a GPU-shaped pool as well as the default one, because the default renders `gpus []`, `kubelet {}` and `instanceType ""` as falsy and a consumer reading a subset of the group is indistinguishable there from one reading all of it; on an explicit `kernelModules` list, which neither of those shapes sets; and a last case pins that the shapes hash differently, so the others cannot hold vacuously. Verified by injecting each divergence: dropping `gpus` at one call site, dropping `kernelModules` at one call site, and pointing the Role back at `<release>-<group>` each fail it, the last one also failing the Role cases in `talos_tct_immutable_test.yaml`, as does pointing the `delete` back at the fixed name. - `hack/cozytest.sh hack/talos-reconcile-heredoc_test.bats` passes, the Proxmox cases included. This is the execution-level evidence that the escaping survived the move into `_talosconfigtemplate.tpl`: it renders with a hostile `registryMirrors` endpoint and a hostile `installerRepository`, runs the extracted heredoc through a real shell, and asserts the values come out literal rather than command-substituted; hostile `schematicID` and `version` values, and `proxmox.dnsServers` entries that are not addresses, are asserted refused at render; and the Proxmox heredoc is asserted to emit the nameservers it was given. A rendered-string regex cannot catch a heredoc the shell refuses to emit; this does. - `make generate` in `packages/apps/kubernetes-nodes` — no diff. - The "byte-identical to `main`" claim was measured against `main` on six pool shapes: default, GPU, an explicit `kernelModules` list, `kernelModules: []` on a GPU pool, `osImage.factory` and Proxmox. For each, the `TalosConfigTemplate` manifest the Job applies differs only in its name (`${RELEASE}-${GROUP_NAME}` → `${TCT_NAME}`); the spec is unchanged, the Job's `TCT_NAME` equals the `MachineDeployment`'s `configRef.name`, and the `KubevirtMachineTemplate` and `ProxmoxMachineTemplate` names do not move. - **Not verified:** no live-cluster or e2e run (needs bare-metal nodes). The upgrade sequence above, the scaling freeze included, comes from reading the CAPI v1.10.1 `MachineDeployment` controller source and the chart's existing `KubevirtMachineTemplate` precedent, not from watching it end to end. ### Downstream repositories - [ ] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: Every box is left empty on purpose, including the first, because I am not confident about one line of the map and would rather a maintainer decided than have me tick it. The change adds no field and changes no default: the only schema movement is the description text of `talos.registryMirrors` and `kernelModules`, regenerated from their `values.yaml` doc comments. Nothing else downstream restates this chart's templates, the hash naming is internal to the chart, and no image reference, CI behaviour or CRD shape moves. The open question is whether `terraform-provider-cozystack` restates field descriptions as well as field shapes; if it does, those description changes reach it and want a follow-up. ## Release note ```release-note fix(kubernetes): name the worker TalosConfigTemplate after a hash of its content so machine-config changes (searchDomains, certSANs, registries, nameservers) actually propagate instead of being silently rejected by the immutability webhook. Upgrading rolls existing Talos workers once, on KubeVirt and Proxmox pools alike. Until the talos-reconcile Job has created the new template, the pool cannot scale, so a failed talos-reconcile Job now blocks cluster-autoscaler scale-up and scale-down while the HelmRelease stays Ready; check the MachineDeployment's ScalingUp condition ("blocked because TalosConfigTemplate does not exist") and the Job status, which is deleted ten minutes after it fails. On a node group holding a scarce resource such as GPUs, review the MachineDeployment surge settings and the MachineHealthCheck nodeStartupTimeout first: `maxSurge: 0` can deadlock the roll and the default startup timeout can trigger spurious remediation while machines queue for the resource. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Worker Talos configuration templates now use content-hashed names for consistent reconciliation and bootstrap references. * Changes to worker machine configuration, including GPU and registry mirror settings, automatically roll existing workers. * **Documentation** * Updated registry mirror documentation to explain that configuration changes roll all workers in the pool. * **Tests** * Added coverage for hashed template names, configuration-triggered worker rotations, and matching references across worker resources. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Yan Bondarenko
|
2fa7fea29b |
fix(dashboard): show ConfigMaps listed in the application resource map
FoundationDB keeps its connection string in a ConfigMap that its operator writes, and tenants may read it, but the console had no view for ConfigMaps. Tenant roles grant ConfigMaps by name only, so the tab takes the names from the application's resource map and reads each one with a metadata.name field selector, which RBAC checks against resourceNames. An application without a readable resource map shows no tab, while a listed ConfigMap that cannot be read is reported instead of looking empty. Assisted-by: LLM Signed-off-by: Yan Bondarenko <202671653+yankawai@users.noreply.github.com> |
||
|
Yan Bondarenko
|
e3ae8033e6 |
fix(foundationdb): let tenants read the dashboard resource map
The resource map is the only object that names the connection ConfigMap for a client such as the dashboard. It was rendered only with monitoring enabled, and the tenant role could not read it, so a tenant session had no way to find the ConfigMap it is allowed to read. Assisted-by: LLM Signed-off-by: Yan Bondarenko <202671653+yankawai@users.noreply.github.com> |
||
|
Yan Bondarenko
|
46b5a542fe |
fix(api): let the garbage collector finalize Applications
An Application and its HelmRelease share one UID, so the garbage collector keeps a single graph node for both and may finalize it through the Application endpoint. The API never returned finalizers on an Application, and every update restored the HelmRelease finalizers from the live object. When the collector came to drop foregroundDeletion or orphan through the Application, removeFinalizer found no such finalizer and returned as if it were already gone. The HelmRelease then kept foregroundDeletion after Helm had uninstalled the release, and the deletion never completed. The Application now carries the two garbage collection finalizers, and an update that adds or removes one of them applies the same change to the HelmRelease. Controller finalizers such as finalizers.fluxcd.io stay owned by the live object, so helm uninstall still runs before the release goes away. The deletion timestamp and grace period are copied from the live object, which keeps an update of a terminating release valid. Assisted-by: LLM Signed-off-by: Yan Bondarenko <202671653+yankawai@users.noreply.github.com> |
||
|
Aleksei Sviridkin
|
4f043b572e |
fix(api): pass the stored object to UpdatedObject in tenantsecret Update (#4603)
## What this PR does A PATCH against an existing TenantSecret returned 404 because `REST.Update` passed `nil` as the old object to `objInfo.UpdatedObject`, and the apiserver patch handler builds the patched object from that old object alone. `Update` now passes the stored Secret (converted with `secretToTenant`) and keeps `nil` only for the `forceCreate` path. The nil also made the patch reach admission as CREATE instead of UPDATE. Validation: the new `TestUpdate_PassesStoredObjectToUpdatedObjectInfo` fails before the change and passes after; `go test ./pkg/registry/...` and `go build ./pkg/... ./cmd/...` pass. I did not run a live `kubectl patch` or the real apiserver patch handler. Known limitation, unchanged by this PR: `tenantToSecret` prefers `Data` over `StringData` when `Data` is non-empty, so a patch that only sets `stringData` on a secret that already has data is a no-op, as a GET-then-PUT edit of `stringData` already is. Patching `data` or metadata works. Fixes #3601 ### Screenshots Not a UI change. ### Downstream repositories - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: - [ ] [cozystack/community](https://github.com/cozystack/community) - follow-up: ### Release note ```release-note fix(api): PATCH, `kubectl label` and `kubectl edit` on an existing TenantSecret no longer fail with 404 NotFound. ``` <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Tenant secret updates now correctly apply changes using the existing stored value, including label updates. <!-- end of auto-generated comment: release notes by coderabbit.ai --> |
||
|
Aleksei Sviridkin
|
3d610b7c31 |
feat(monitoring): add optional email receiver to alertmanager (#3800)
## What this PR does Adds an optional email receiver configured through `alerta.alerts.email`. It is disabled by default. Alerts carrying `notify_email="true"` are emailed when their severity is in `severities`, which defaults to critical and major. `alertnames` also selects platform alerts without changing their rules. Earlier heartbeat and blackhole routes keep precedence. Email routes preserve the Alerta copy through a preceding route with `continue: true`, and they inherit the root `group_by`, so Alerta and email agree on how many notifications one alert produces. The SMTP password is read from a Secret with a fixed name, `alertmanager-email-password`, mounted through `VMAlertmanager.spec.secrets` and referenced by `auth_password_file` when `authUsername` is set. The platform operator creates that Secret. The name is not configurable, because a tenant-chosen name would let a `Monitoring` writer mount any Secret of the namespace into Alertmanager and send its `password` key to an SMTP host of their choosing, and no tenant role can read those Secrets by any other route. `to` takes an address or a comma-separated list, and `from` takes one address, each with an optional display name. The accepted form is narrower than RFC 5322 on purpose, so that a bad address fails the render instead of being dropped when the first alert fires. The local part must be a dot-atom. A display name is a run of atoms or quoted strings without the specials `net/mail` rejects in a phrase. A domain literal must hold a dotted-quad IPv4 address. IPv6 literals are rejected because their syntax differs across Go mail parser versions. Template actions are rejected, because Alertmanager expands both fields as templates before it parses them. Quoted local parts, comments and a pasted `mailto:` prefix fail the render as well. `smarthost` must be `host:port`, where the host is a host name or a bracketed IP address. A bracketed value must be a valid IPv4 or IPv6 address, so `[deadbeef]:25` and `[1:2:3:4::5:6:7:8]:25` fail the render. The port must be between 1 and 65535 and must not have leading zeros, so `smtp.example.org:0465` fails too. `repeatInterval` is checked with Alertmanager's own duration grammar and limits. Units go in descending order, each at most once, and the value must be non-zero and below the int64 overflow, so what renders is what Alertmanager loads. Partial configuration fails the render and names the fields still set, so clearing the addresses to turn email off tells the operator which leftovers to clear. Subject and body templates are not exposed. Alertmanager parses them per notification, and a broken one surfaces only in a log the tenant cannot read. Checks run for this change. - The monitoring chart suites pass with 228 tests in `packages/system/monitoring` and 16 in `packages/extra/monitoring`. 117 of them are in the two email test files. - 234 address inputs were rendered through the chart. 91 were accepted and 143 rejected. Every accepted input executes as a template and passes `net/mail.ParseAddressList`, including the one-address check for `from`, on Go 1.25.8, 1.26.4 and 1.27.1. - Widening the IPv4 octet from `25[0-5]` to `25[0-9]` fails 4 tests. Putting back the loose `\[[0-9A-Fa-f:.]+\]` domain literal fails 19 tests. Replacing the group-count guard for compressed IPv6 smarthosts with `true` fails the `[1:2:3:4::5:6:7:8]:25` test. - `make generate` with cozyvalues-gen v1.6.0 leaves the tree unchanged. SMTP delivery against a real relay has not been tested. ### Screenshots No dashboard/UI change. ### Downstream repositories Walked the trigger map against the diff. `packages/extra/monitoring` gains values fields, so its README and schema changed. `monitoring` is in the website Makefile `SERVICES` list, and that reference page regenerates from `README.md` automatically on the next stable tag, so there is no manual follow-up to link. The terraform provider does not model the monitoring service, as there is no such resource under `internal/provider`, so there is nothing to update there either. No package is added or renamed, and no CRD, tooling or node contract is touched. - [x] No downstream repository is affected by this change - [ ] [cozystack/website](https://github.com/cozystack/website) - follow-up: - [ ] [cozystack/terraform-provider-cozystack](https://github.com/cozystack/terraform-provider-cozystack) - follow-up: - [ ] [cozystack/ansible-cozystack](https://github.com/cozystack/ansible-cozystack) - follow-up: - [ ] [cozystack/ccp](https://github.com/cozystack/ccp) - follow-up: - [ ] [cozystack/talm](https://github.com/cozystack/talm) - follow-up: - [ ] [cozystack/cozyhr](https://github.com/cozystack/cozyhr) - follow-up: - [ ] [cozystack/cozy-proxy](https://github.com/cozystack/cozy-proxy) - follow-up: - [ ] [cozystack/cozystack-telemetry-server](https://github.com/cozystack/cozystack-telemetry-server) - follow-up: - [ ] [cozystack/external-apps-example](https://github.com/cozystack/external-apps-example) - follow-up: - [ ] [cozystack/examples](https://github.com/cozystack/examples) - follow-up: ### Release note ```release-note feat(monitoring): add optional email alerting through alerta.alerts.email, with configurable severity and alert-name selection and an SMTP password read from the fixed Secret alertmanager-email-password ``` |
||
|
Aleksei Sviridkin
|
8b8d4115fc |
fix(workloadmonitor): stop panicking on a PVC without a storage class
The storage class check used || where it needed &&, so a PVC with no storageClassName (one that takes the cluster default) was dereferenced as a nil pointer. controller-runtime recovers the panic, but the reconcile of that WorkloadMonitor fails on every retry and never reaches its status update. A PVC with an empty storageClassName produced a resource key with an empty class name instead of falling back to "default". Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Aleksei Sviridkin
|
a905fef9dd |
fix(clickhouse): use the cluster domain in keeper node hostnames
The zookeeper block redeclared $clusterDomain from .Values.clusterDomain, a value the chart never defines, so it shadowed the template-level variable read from _cluster.cluster-domain and every keeper host rendered as "<pod>.<namespace>.svc." with no domain. Keeper is enabled by default, so this hit every ClickHouse release. The keeper name test set clusterDomain itself, which hid the bug; it now supplies only _cluster.cluster-domain, as the platform does. Assisted-by: LLM Signed-off-by: Aleksei Sviridkin <f@lex.la> |
||
|
Yan Bondarenko
|
17aaf3e038 |
feat(monitoring): add optional email alert delivery
Platform alerts need an email delivery path alongside Alerta without exposing arbitrary namespace Secrets through tenant-controlled values. SMTP credentials therefore use a fixed Secret name. Alertmanager parses the addresses and connects to the SMTP host only when it sends a notification, so a malformed value there drops alerts instead of failing the release. The chart validates these fields when it renders. Addresses must be literal dot-atom mailboxes, and a domain literal must hold a dotted-quad IPv4 address, because IPv6 literal syntax differs across the supported Go mail parsers. A bracketed smarthost must be a valid IPv4 or IPv6 address, and its port must be between 1 and 65535 without leading zeros. The repeat interval follows the Alertmanager duration grammar and range, so a value that renders is one Alertmanager loads. Signed-off-by: Yan Bondarenko <202671653+yankawai@users.noreply.github.com> Assisted-by: LLM |
||
|
Yan Bondarenko
|
bd2cc0a749 |
test(monitoring): guard alert severities against the Alerta alarm model
Alerta refuses an alert whose severity is not in its alarm model, so a rule with such a label is dropped every time it fires and the alert never reaches anyone. Seven piraeus-datastore rules used warn and the keda at-max rule used info, and nothing in the tree caught either. The contract collects every PrometheusRule and VMRule document under packages, in alerts files and in chart templates, and fails on any alerting rule whose labels.severity is missing or not in the accepted list. Helm actions are stripped before parsing, so a templated rule is still checked, and a file that cannot be parsed fails the run instead of being skipped. Values are compared as whole words. none stays out of the list because the Alertmanager config routes it to a blackhole receiver. Vendored charts under packages/**/charts/** are out of scope because they are re-vendored rather than edited. Signed-off-by: Yan Bondarenko <202671653+yankawai@users.noreply.github.com> Assisted-by: LLM |
